## What changed

Introduce `ItemIdGenerator` and pass the runtime-owned generator through sessions, model clients, history, hooks, tool outputs, and memory requests. Keep UUIDv7 generation as the default and replace direct calls to `ResponseItemId::new` with the shared callable.

Preserve existing item IDs and backfill missing or empty IDs through the same generator, including forked history before reconstruction and persistence.

## Testing

Extend coverage for UUIDv7 IDs on user messages, agent messages, and additional tools, and assert that forked model context matches the backfilled items persisted to history.

GitOrigin-RevId: 0dd9ccf0f46f0f1005a6acfc740133b03ce82259
## What changed

- Share a lazily registered runtime across threads, model discovery, and extension clients when `runtime_agent_instances` is enabled, while honoring each thread's authentication mode and credential owner.
- Bind model catalogs to the effective provider and authentication context while preserving cache policy and live API-key discovery settings.
- Resolve credentials, routing, and transport policy together for each request. Preserve proxy and TLS settings, validate runtime account selectors, and prevent pooled connections from crossing runtime identities.
- Accept supported ChatGPT subdomains when selecting the registration environment.

## Testing

Add integration coverage for shared runtime registration, dual-header and assertion-only modes, disabled and third-party providers, credential replacement, subagents, and delegated review. Add coverage for catalog cache policy and runtime-aware connection reuse.

GitOrigin-RevId: 99dd9d987c29c93597a648f6586f98ac6a932c3c
## What changed

Return `CatalogModel` from model lookups, keeping metadata together with its `Bundled`, `Provider`, `ExplicitConfig`, or `Synthetic` origin through config overrides and runtime snapshots. Replace `used_fallback_model_metadata` checks with explicit `Synthetic` origin checks.

Share the underlying `Arc<ModelInfo>` with extension stores and use copy-on-write for metadata changes. Keep origin tracking outside serialized model metadata.

## Testing

Extend coverage for origin retention across cache reloads, namespaced model lookups, catalog fallback, and config overrides. Verify that step snapshots and extension stores share the same model metadata allocation.

GitOrigin-RevId: bb6130c94a7a795aa168ee24664a1dd453579fba
## What changed

Add `otel.log_sse_deltas`, enabled by default. Setting it to `false` suppresses successful SSE event logs whose kind ends in `.delta` while preserving errors, completion events, and metrics.

Apply the setting to session and memory telemetry, support managed requirements, and expose it in the app-server configuration requirements API and generated schemas and bindings.

## Testing

Add coverage for delta log suppression with errors, completion logs, event counts, and duration metrics preserved. Extend configuration and app-server tests to cover defaults, overrides, and managed requirements.

GitOrigin-RevId: 751c7f357c41f51848b025c838246a733eb92e2f
## Why

Concurrent imports and consolidation can modify the same memory workspace, leaving a partial import across memory versions or interfering with consolidation snapshots and baselines.

## What changed

- Add a cross-process workspace lock shared by memory imports and consolidation.
- Acquire locks for every import destination before modifying any workspace. Return a retryable busy error if a destination is locked, and skip consolidation when its workspace is busy.
- Hold locks through import completion even if the caller drops the future, and through consolidation agent termination and baseline finalization.

## Testing

Add an app-server integration test that blocks an active consolidation, verifies import rejection without partial writes or snapshot changes, then retries successfully and confirms imported resources remain visible to the next consolidation.

GitOrigin-RevId: c4ce945f916dcb4d75a3190ea869751fac51de83
## What changed

- Add the disabled-by-default `output_token_replay` feature to request `output.encrypted_content` from OpenAI providers.
- Preserve encrypted message and tool-call output, message and function-call status, and output-text `annotations` and `logprobs` through history and replay. Update the generated protocol schemas and SDK types.
- Strip output ciphertext from requests to other providers while retaining it in stored history, including after replay is disabled. Remove encrypted content from memory extraction inputs.

## Testing

Add integration coverage for the feature/provider combinations, metadata replay across follow-up requests, and history preservation when resuming with replay disabled.

GitOrigin-RevId: 77729a021b6771933402aebe74ece8eb39c057e2
## What changed

Add `ModelRequestContributor` and `ModelResponseInterceptor` to the extension API. Contributors can add filtered `client_metadata` without overwriting existing or reserved fields and create interceptors for individual requests.

Wire contributors into HTTP and WebSocket requests, distinguishing generation from warmup. Apply response interceptors in registration order before tracing and response bookkeeping so transformed output is recorded consistently. Interceptors can inspect, buffer, or transform events, with stream ownership carrying request state and cancellation.

## Testing

Add tests for metadata protection, incremental event transformation, interceptor ordering, upstream cancellation, and consistency between delivered output, traces, and WebSocket bookkeeping. Integration tests cover output gating and interruption over HTTP and WebSocket, including a contributor that bypasses gating for warmup requests.

GitOrigin-RevId: d4bc1745d2cacf8636728dbc0a58ab9f250e9392
## Why

Resuming a thread after disabling reasoning effort overrides still sent saved `configuration_update` items until compaction. Disabling the feature should also apply to requests built from existing history.

## What changed

Pass the `ReasoningEffortOverride` feature state into `ModelClient` and filter `configuration_update` items from request input when disabled. Preserve persisted history and other input items while using the request-level reasoning effort.

## Testing

Add regression coverage for resumed threads, compaction, and WebSocket warmup and turn requests. Verify that saved updates remain in history and `agent_message` items remain in request input.

GitOrigin-RevId: aac3257da1ca38a0744807c4f7cb12565bd7fe53
## What changed

Emit a `codex.memory.storage_bytes` histogram after successful phase-two consolidation, including runs with no workspace changes. Sum regular-file sizes recursively from filesystem metadata, excluding `.git` entries and symbolic links. Stop the phase-two duration timer before measuring storage.

## Testing

Add coverage for both memory versions, nested files, UTF-8 byte counts, Git metadata exclusion, and Unix symbolic links, including broken links and directory loops. Extend the workspace baseline reset test to verify the remaining storage size.

GitOrigin-RevId: 9170c34d656728897790decd2e2cabb38a81836f
## What changed

- Add an optional `WorkspaceRoutingResolver` to `AuthManager` and pass session configuration into routing lookups. Callers without a resolver retain existing routing behavior.
- Apply resolved backend origins and account routing overrides to eligible ChatGPT Responses HTTP requests and WebSocket handshakes. Preserve endpoint paths, validate routing values, and reject HTTP redirects for routed requests, including `NO_CONSTRAINT` routes.
- Key cached WebSocket connections by destination, routing header, and auth revision. Rebuild request setup after credential refreshes and reject account changes during setup or routing discovery.
- Serialize routing lookups per session and retain whether the session has previously been routed.

## Testing

Add tests for path preservation, provider exclusions, concurrent routing lookups, unavailable resolvers, workspace mismatches, redirect rejection, and credential refresh or account changes during request setup.

GitOrigin-RevId: 2b6609019e84a315745c94858955f3f16426fe7f
## What changed

Populate `turn_trigger` in request metadata with `guardian_review` for guardian reviews, `guardian_classifier` for classifier requests, and `memory_consolidation` for both detached memory requests and consolidation agent turns.

## Testing

Extend request metadata assertions to cover each trigger across guardian reviews, classifier requests, and both memory startup phases.

GitOrigin-RevId: 2dc3c173ede6563b942b8099ad9901c32967b969
## Why

Allow v2 memories to build in the background while the selected memory version continues supplying context, and let clients check whether v2 has enough consolidated data and a valid summary to use.

## What changed

- Add `memories.dual_write`, disabled by default, to run v1 and v2 extraction and consolidation concurrently with separate stores and directories.
- Add the experimental `memory/status` endpoint, returning `v2ConsolidatedThreads` and `v2Ready`. Readiness requires a valid v2 summary and a consolidation thread count meeting `minConsolidatedThreads` (default 20, supported range 1–4096).
- Persist the largest thread count from a successful consolidation across pruning and clear it on memory reset.
- Share v2 summary validation between consolidation and status reporting, and tag memory metrics with `memory_version`.

## Testing

Add tests for independent dual-write outputs, preserving existing notes without importing them into v2, and readiness behavior across consolidation ownership checks, missing summaries, configurable thresholds, thread deletion, and memory reset.

GitOrigin-RevId: 54417cc60bf419062401355c0da8c79119995f61
## What changed

- Add `memories.version` with `v1` as the default and `v2` as an opt-in selection.
- Route memory generation, summaries, and retrieval tools through the selected version. Store `v2` artifacts in `memories_v2` and lazily create a separate SQLite database, keeping jobs and outputs isolated while sharing the thread catalog.
- Preserve the initial memory version across extension config updates so summaries and retrieval tools use the same namespace.
- Clear both versions on memory reset and remove thread memory from both stores on thread deletion. Recognize both artifact roots in shell usage telemetry.

## Testing

Add regression coverage for version defaults and validation, independent job claims and outputs, deletion and reset across versions, and shell usage classification for both memory roots.

GitOrigin-RevId: aa799bf87ab6ec10c8f5668213931e57547d080b
## Why

Git root discovery is optional metadata work, but filesystem probes can block. They should not exhaust Tokio's blocking pool, delay runtime shutdown, or prevent later turns from observing repository changes.

## What changed

- Add a shared `GitRootDiscovery` service that coalesces concurrent lookups for the same working directory and limits probes across directories.
- Run probes on detached threads, retain in-flight work across caller cancellation, and discard completed results instead of caching them.
- Use the service for turn and memory metadata enrichment, abort unused turn enrichment when its state is dropped, and limit memory metadata waits to one second.

## Testing

Add coverage for probe sharing, capacity limits, cancellation, fresh discovery, runtime shutdown, memory timeouts, and repositories restored after startup prewarming.

GitOrigin-RevId: bca46fc263e7a12a2f69146d8a0b3e7c7e0846cb
## What changed

- Add the under-development `content_item_kinds` feature, disabled by default.
- Strip content item classifications from Responses input when the feature is
  disabled while preserving other passthrough metadata.

## Testing

- Add coverage that disables the feature and verifies requests omit content item
  kinds without removing the turn ID.

GitOrigin-RevId: f938feb2895d766d979b1666fc7b97fd128fe8a7
## Why

Environment-owned permission profiles and workspace roots must remain effective
without being persisted or restored as thread-owned settings.

## What changed

- Keep thread settings snapshots and restore data separate from the effective
  configuration supplied by the primary environment.
- Use resolved environment permissions, active profiles, workspace roots, and
  network policy when building turn context and session events.
- Preserve environment selections when agents are evicted, resumed, or spawned,
  and validate owner configuration when it becomes ready.
- Start memory initialization only after the primary environment is configured.

## Testing

- Extend remote-environment and multi-agent tests to cover settings persistence,
  owner permission profiles, workspace roots, spawning, eviction, and resume.

GitOrigin-RevId: d82f126981cd0190233020bbdd61d96c70558868
## What changed

- Add `TurnInputRequest` and typed submission results for atomically starting a turn, steering the active turn, or declining input with a specific reason.
- Expose `start_or_steer_turn`, `start_turn_if_idle`, and `steer_turn` on `CodexThread`, and migrate Core consumers to these APIs.
- Make app-server `turn/start` steer an active regular turn and return that turn's ID. Reject incompatible output schemas and non-steerable turns without applying settings or enqueueing input.

## Testing

- Cover concurrent start-or-steer submissions, accepted and rejected settings updates, output-schema compatibility, idle-start rejection, and app-server steering.

GitOrigin-RevId: dd9b5528d76ec650c019e97af420bc13190ea86a
## What changed

- Add the effective permission profile as `sandbox_mode` in turn metadata for regular, prewarm, compaction, and detached memory requests.
- Reserve `sandbox_mode` so client-provided metadata cannot override the computed value.

## Testing

- Cover metadata headers and request bodies for read-only and danger-full-access modes.

GitOrigin-RevId: 13c690cc99bc2691023f281ca527af049bb1286f
## Why

A phase-two memory job could release its lease while its consolidation agent was
still shutting down, allowing another worker to race the existing agent.

## What changed

- Await consolidation-agent shutdown before validating artifacts and completing
  the job.
- Keep the lease until it expires if shutdown fails, and remove the agent from
  the thread manager only after shutdown succeeds.

## Testing

Update startup tests to wait for the phase-two job lifecycle to finish and verify
that the consolidation thread has been removed.

GitOrigin-RevId: 7ac3a7369529822ac95fd2ee9dcb27d39c191d20
## What changed

- Add `StartThreadOptions::new` to provide the standard configuration for a new thread.
- Make `ThreadManager::start_thread` the single thread-start entry point and migrate callers from the previous convenience methods.
- Derive default environment selections when `environments` is `None`, while preserving explicit selections, including an empty list.

GitOrigin-RevId: 8977dc11aed54c5e1215a81eaed2b2cf5fc6087a
## What changed

- Assign IDs to client-created response items in every session, including streamed items, forked history, compaction results, and non-OpenAI provider requests.
- Preserve server-provided IDs and stable generated IDs across persisted and resumed conversations while continuing to omit unprefixed server IDs from outbound requests.
- Retire `features.item_ids` as a configurable feature. Existing configuration and CLI toggles remain accepted as compatibility no-ops.

## Testing

- Cover default ID assignment, persistence and resume behavior, remote compaction, provider requests, WebSocket requests, and removed-feature compatibility.

GitOrigin-RevId: 7a09e2d07d2606c2ef1e8e2283d36cb555557eae
## Why

Multi-environment turns can run against different filesystems, so a single
thread-wide workspace-root list cannot accurately describe every selected
environment.

## What changed

- Add optional `runtimeWorkspaceRoots` to each app-server environment selection.
  Omitted roots default to that environment's `cwd`, while an empty list selects
  no roots.
- Carry environment-native roots through turn selection, model-visible context,
  permission materialization, and tool sandboxing.
- Keep the top-level `runtimeWorkspaceRoots` field as a compatibility input when
  constructing default environment selections; explicit selections use their
  own roots.

## Testing

- Cover thread and turn API defaults, overrides, empty roots, and schema
  round-tripping.
- Verify foreign roots remain model-visible and remote execution applies the
  target environment's roots before sandbox selection.

GitOrigin-RevId: c6e7a62883c45c676c153055f46a55ee15a323a4
## Why

`features.respect_system_proxy` already routes authentication traffic
through the OS proxy APIs, but it does not affect the primary inference
path. That leaves users behind OS-managed proxies unable to send normal
Responses API requests even after login succeeds.

This PR is the first product-path migration onto the route-aware
transport introduced in #31323 and refined in #31331. It also
establishes the construction pattern for later migrations: the effective
feature state is resolved once into a required HTTP client factory
rather than represented by an optional per-call setting.

The scope remains limited to the two HTTP Responses endpoints;
WebSockets, model discovery, memories, realtime, and file uploads remain
follow-up migrations.

## What changed

- Replace the optional proxy marker with an explicit
`OutboundProxyPolicy::{ReqwestDefault, RespectSystemProxy}` and a
required `HttpClientFactory`. The policy has no default, and the
lower-level route-aware reqwest builder is now private.
- Have `Config` construct the factory from the effective feature state
and require every `ModelClient` constructor to receive it. There is no
optional setter or implicit `None` fallback.
- Build HTTP clients for `/responses` and `/responses/compact` with
`ClientRouteClass::Api`, using the complete destination URL so PAC rules
can make URL-specific decisions.
- Layer route-aware selection onto Codex's existing default headers,
Cloudflare cookie store, custom CA handling, and sandbox no-proxy
behavior.
- Add an integration test that loads `features.respect_system_proxy`
through `config.toml`, creates a real Codex session, and verifies that
both a normal Responses turn and remote compaction reach an isolated
local proxy.

## Review guide

1. `http-client/src/outbound_proxy.rs` defines the mandatory
policy/factory boundary and keeps route resolution private.
2. `core/src/config/mod.rs`, `core/src/session/session.rs`, and
`core/src/client.rs` show the compile-time invariant: effective config
creates the factory, and `ModelClient` cannot be constructed without
one.
3. `login/src/auth/default_client.rs` preserves existing default-client
behavior while accepting the required factory for migrated routes.
4. `core/src/client.rs` switches only streaming Responses and remote
compaction HTTP transports to the API route class.
5. `core/tests/suite/responses_api_system_proxy.rs` is the behavioral
regression boundary. Its Linux subprocess deliberately sets the CGI
marker that disables reqwest's implicit environment-proxy handling, so
the test fails if session wiring or either Responses call site falls
back to the default client.

## Test plan

- `cargo check --tests -p codex-http-client -p codex-login -p
codex-core`
- `just test -p codex-login`
- `just test -p codex-core
respect_system_proxy_feature_resolves_enabled`
- Existing `compact_uses_bearer_after_agent_identity_session_fallback`
coverage passes with the new transport construction.
- New Linux integration coverage:
`responses_and_compact_use_enabled_system_proxy`
- `just bazel-lock-check`

---
[//]: # (BEGIN SAPLING FOOTER)
Stack created with [Sapling](https://sapling-scm.com). Best reviewed
with [ReviewStack](https://reviewstack.dev/openai/codex/pull/31335).
* #31342
* __->__ #31335
## Summary

When enabled for the OpenAI provider, Codex sends
`stream_options.reasoning_summary_delivery = "sequential_cutoff"` on
HTTP and
WebSocket requests, including prewarm, and renders completed summary
sections
from `reasoning_summary_text.done`. Flag-off and non-OpenAI behavior is
unchanged.

## Expected rollout

```text
reasoning 0 added
summary 0 done
summary 1 done
summary 2 starts
summary 2 cancelled / incomplete
reasoning 0 done  <-- cancel summary 2 work and mark it incomplete
message 1 added
message 1 text streams
message 1 completed
```

Depends on
[openai/openai#1096660](https://github.com/openai/openai/pull/1096660).
## Description

This PR adds a new `historyMode = "legacy" | "paginated"` to `Thread`.
This will be stored in `SessionMeta` in the JSONL rollout file and as a
new column in the SQLite thread_metadata table, and exposed on
`thread/start` and on the `Thread` object in app-server.

## What changed

- Added canonical `ThreadHistoryMode` with `legacy` and `paginated`,
defaulting old and new SessionMeta to `legacy`.
- Carried `history_mode` through core session config, ThreadStore stored
metadata, local/in-memory stores, rollout metadata extraction, and the
existing SQLite `threads` table.
- Added experimental `historyMode` to app-server v2 `Thread` and
`thread/start`.
- Made paginated stored threads metadata-discoverable but unsupported
for legacy full-history reads, `load_history`, live resume, and create
paths.
- Regenerated app-server schema fixtures and added
protocol/state/thread-store/app-server coverage for persistence and
fail-closed behavior.

## Compatibility floor
Because users may be running various versions of Codex binaries on the
same machine (TUI, Codex App, etc.), we will need to establish a
compatibility floor for upcoming paginated threads, which will change
how thread storage reads and writes work.

The overall plan here:
```
Release N:
- Add historyMode to SessionMeta / Thread / SQLite metadata.
- Teach binaries to understand paginated threads.
- If a binary sees `historyMode="paginated"` but does not support the paginated contract, it refuses to resume/mutate the thread.
- Default remains `"legacy"`.

Release N+1:
- First-party clients start opting into paginated threads where appropriate.
- Internal dogfood / staged rollout.
- Measure old-client usage and paginated-thread unsupported errors.

Release N+2:
- Only after Release N+ is overwhelmingly deployed, make paginated the default.
- Accept that a small tail of N-1-or-older binaries may not understand paginated threads.
```

The important behavior change is fail-closed handling for a binary that
encounters a persisted `paginated` thread before it knows how to fully
support paginated history. In app-server, if a thread is `paginated`, we
will:

- allow metadata-only discovery paths like `thread/list` and
`thread/read(includeTurns=false)`, so clients can still see the thread
and inspect its `historyMode`
- reject legacy full-history/live-thread paths like
`thread/read(includeTurns=true)` and `thread/resume` with an unsupported
JSON-RPC error
- avoid silently treating an unknown or future `historyMode` as `legacy`

Under the hood, the ThreadStore layer also rejects legacy operations
that would need to load or replay the full thread history for a
paginated thread. That gives us the behavior we want for Release N:
future paginated threads are visible, but this binary fails closed
instead of trying to operate on them as if they were legacy threads.
## Why
Helper threads such as task title generation can request a model ID that
is valid for the default OpenAI provider but unavailable from the active
provider. With Amazon Bedrock, `gpt-5.4-mini` is rejected while the
provider static catalog exposes Bedrock model IDs such as
`openai.gpt-5.5` and `openai.gpt-5.4`. This causes repeated background
404s and can surface a misleading turn error even when the main turn
succeeds.
Clients need an explicit way to ask app-server to resolve an unavailable
helper model to the active provider default. That fallback must remain
limited to providers with an authoritative static catalog so custom or
dynamically discovered model IDs are not rewritten based on an
incomplete catalog.
Fixes#28741.
## What changed
- Add the experimental `allowProviderModelFallback` option to
`thread/start`, defaulting to `false` to preserve existing behavior.
- Thread the option through thread creation and model selection.
- When enabled for a static model manager, preserve requested models
present in the catalog and replace unavailable models with the provider
default.
- Continue preserving explicit model IDs for dynamic model managers
without fetching a catalog solely to validate them.
- Document the new `thread/start` behavior in the app-server API
overview.
## Test
Temporary test-client harness:
```
ThreadStartParams {
model: Some("gpt-5.4-mini".to_string()),
allow_provider_model_fallback: true,
..Default::default()
}
```
Command:
```
CODEX_HOME=/tmp/codex-bedrock-thread-start-home \
CODEX_E2E_BEDROCK_THREAD_START_ONLY=1 \
./target/debug/codex-app-server-test-client \
--codex-bin ./target/debug/codex \
-c 'model_provider="amazon-bedrock"' \
send-message-v2 --experimental-api ignored
```
Relevant output:
```
> "method": "thread/start",
> "params": {
> "model": "gpt-5.4-mini",
> "modelProvider": null,
> "allowProviderModelFallback": true,
> ...
> }
< "result": {
< "model": "openai.gpt-5.5",
< "modelProvider": "amazon-bedrock",
< ...
< }
```
## Stack

This is PR 3 of the simplified HAI single-run-task stack:

- [#19047](https://github.com/openai/codex/pull/19047) Agent Identity
assertion and task-registration primitives, including the shared
run-task helper used by existing Agent Identity JWT auth.
- [#19049](https://github.com/openai/codex/pull/19049)
Disabled-by-default ChatGPT auth opt-in that provisions/reuses persisted
Agent Identity runtime auth and its single run task.
- [#19051](https://github.com/openai/codex/pull/19051) Run-scoped
provider auth that uses one backend-owned task id for first-party
inference and compaction requests.

[#19054](https://github.com/openai/codex/pull/19054) collapsed out of
the active stack because the simplified design no longer needs a
separate background/control-plane task helper.

## Summary

This PR moves Agent Identity usage into provider auth resolution. That
keeps `AgentAssertion` auth tied to first-party OpenAI provider requests
instead of applying a late session-wide override that could affect
local, custom, Bedrock, API-key, or external-bearer providers.

What changed:

- adds a small `ProviderAuthScope` struct carrying the run auth policy
and session source needed by provider-scoped auth resolution
- lets `Session` opt the existing `ModelClient` into `ChatGptAuth`
policy when `use_agent_identity` is enabled, without adding a second
model-client constructor
- resolves Agent Identity only for first-party OpenAI provider auth
paths
- uses the persisted run task id from the `AgentIdentityAuth` record to
build `AgentAssertion` auth for Responses requests
- routes shared request setup through scoped provider auth so unary
compact requests use the same run-task assertion path as inference turns
- keeps local/custom/Bedrock/env-key/external-bearer provider auth
unchanged
- lets missing run-task state surface through the existing model-request
error path instead of silently falling back to bearer auth

This PR intentionally does not create thread-scoped, target-scoped, or
background-scoped task identities. The run task is the only task Codex
registers in this POC shape.

## Testing

- `just test -p codex-model-provider`
- `just test -p codex-core client::tests::provider_auth_scope_uses`
- `just test -p codex-core remote_compact_uses_agent_identity_assertion`
## Why

Ultra should be one user-facing reasoning selection for work that
benefits from both maximum reasoning and proactive multi-agent
delegation. Without it, clients must coordinate maximum reasoning with
the experimental `multiAgentMode` setting, even though the inference
backend still expects its existing `max` effort value.

This change makes reasoning effort the source of truth: clients select
`ultra`, core derives proactive multi-agent behavior when the turn is
eligible for multi-agent V2, and inference requests continue to use the
backend-compatible `max` value.

## What changed

- Add `ultra` as a first-class reasoning effort and preserve
model-catalog ordering when exposing it to clients.
- Convert `ultra` to `max` at the inference request boundary, including
Responses HTTP/WebSocket requests, startup prewarm, compaction, and
memory summarization.
- Derive effective multi-agent mode per turn from effective reasoning
effort:
  - eligible multi-agent V2 + `ultra` → `proactive`
  - eligible multi-agent V2 + any other effort → `explicitRequestOnly`
- V1 or otherwise ineligible sessions → no multi-agent mode instruction
- Keep the derived effective mode in turn context history so successive
turns can emit a developer-message update only when the effective mode
changes.
- Remove selected multi-agent mode from core session configuration, turn
construction, thread settings, resume/fork restoration, and subagent
spawn plumbing. Subagents inherit reasoning effort and derive their own
effective mode.
- Retain the experimental app-server `multiAgentMode` fields for wire
compatibility while marking them deprecated. Request values are accepted
but ignored; compatibility response fields report `explicitRequestOnly`.
- Display Ultra in the TUI using the order supplied by `model/list`.

## Validation

- `just test -p codex-core ultra_reasoning_uses_max_for_requests`
- `just test -p codex-tui model_reasoning_selection_popup`
## Why

Work(TPP) threads can be launched from the Desktop app, but if they all
keep the Desktop app's default originator then downstream attribution
cannot distinguish local Work launches from cloud-backed Work launches.
`thread/start.serviceName` already carries that launch signal, while
`SessionMeta.originator` is the durable thread-level value that survives
resume and fork.

This change converts the Desktop Work service names into an effective
originator at thread creation time, persists that originator with the
thread, and keeps using it for later model requests and memory writes.

## What changed

- Map `CODEX_WORK_LOCAL` and `CODEX_WORK_CLOUD` service names to
per-thread originators, while preserving
`CODEX_INTERNAL_ORIGINATOR_OVERRIDE` as the highest-precedence override.
- Persist the effective originator in `SessionMeta.originator`, read it
back on resume/fork, and inherit the parent originator for subagent
spawns when there is no persisted session metadata.
- Handle truncated `SpawnAgentForkMode::LastNTurns` forks by falling
back to the live parent originator when the forked history no longer
includes `SessionMeta`.
- Thread the per-thread originator through Responses headers,
websocket/compaction request paths, thread-store creation, rollout
metadata, and memory stage-one telemetry.

## Verification

- `just test -p codex-core
agent::control::tests::spawn_thread_subagent_inherits_parent_originator_without_fork
agent::control::tests::spawn_thread_subagent_fork_last_n_turns_inherits_parent_originator_without_session_meta
thread_manager::tests::originator_override_precedes_service_name_remapping`
- `just test -p codex-core
agent::control::tests::resume_thread_subagent_restores_stored_metadata_and_effective_multi_agent_mode`
- `just test -p codex-memories-write`
- `just fix -p codex-core -p codex-memories-write`
- `git diff --check`
## Why

Once multi-agent mode can be selected per turn, clients also need to
choose the initial selection when creating a thread and observe that
selection through lifecycle and settings APIs.

The selected value is intentionally distinct from the effective
model-visible value: no client selection is represented as `null`, even
though an eligible multi-agent v2 turn derives `explicitRequestOnly` as
its effective default.

## What changed

- Add the optional experimental `thread/start.multiAgentMode` parameter
and pass it through thread creation.
- Preserve an omitted initial value as an unset selection rather than
eagerly storing `explicitRequestOnly`.
- Apply an explicit `thread/start` selection to the first turn through
the session configuration established at thread creation.
- Restore the latest persisted effective mode as the selected baseline
on cold resume when rollout history contains one.
- Inherit the optional selected mode from a loaded parent when creating
related runtime threads.
- Return the current selected `multiAgentMode` from `thread/start`,
`thread/resume`, `thread/fork`, and thread settings, using `null` when
no mode is selected.
- Keep lifecycle reporting independent from model capability and feature
eligibility; core turn construction remains responsible for calculating
and persisting the effective mode.

## Not covered

- Clearing an existing loaded-session selection back to unset through
`turn/start`; omitted or `null` currently retains the session's
selection.
- A TUI control, slash command, or `config.toml` preference.

## Verification

- `CARGO_INCREMENTAL=0 just test -p codex-app-server-protocol`
- `CARGO_INCREMENTAL=0 just test -p codex-app-server multi_agent_mode`

The focused app-server coverage verifies explicit `thread/start`
initialization, first-turn prompting, nullable reporting for an omitted
selection, and retention of selections that are not currently
runtime-eligible.

## Stack

Stacked on #28685. This PR contains only the thread initialization and
lifecycle/settings API layer.
## Why

Client-created response items enter history without IDs, so their
identity is lost across rollout persistence and resume. IDs should be
assigned once at the history-recording boundary, while IDs returned by
the server must remain unchanged.

The Responses API validates item IDs using type-specific prefixes.
Locally generated IDs therefore use the matching prefix plus a
hyphenated UUIDv7, keeping them valid while distinguishable from
server-generated IDs. Because this changes persisted history and
provider request shapes, the behavior is opt-in behind the
under-development `item_ids` feature. Compaction triggers remain request
controls whose API shape does not accept an ID.

## What changed

- Register the disabled-by-default `item_ids` feature and expose it in
`config.schema.json`.
- Make supported optional `ResponseItem` IDs serializable and expose
them in the generated app-server schemas.
- When `item_ids` is enabled, assign an ID during conversation-history
preparation if an item has no ID.
- Generate type-prefixed, hyphenated UUIDv7 IDs using the Responses API
item conventions.
- Preserve existing server IDs without rewriting them.
- Persist assigned IDs in rollouts and include them in subsequent
Responses requests.
- Remove the unsupported ID field from `CompactionTrigger` and document
why it has no ID.
- Add integration coverage for enabled ID persistence, preservation of
server IDs, and omission of generated IDs while the feature is disabled.

`prepare_conversation_items_for_history` is the single response-item ID
allocation boundary.

## Test plan

- `just test -p codex-features`
- `just test -p codex-core
response_item_ids_persist_across_resume_and_preserve_server_ids`
- `just test -p codex-core
non_openai_responses_requests_omit_item_turn_metadata`
- `just test -p codex-core
resize_all_images_prepares_failures_before_history_insertion`
- `just test -p codex-protocol`
- `just test -p codex-app-server-protocol`
- `just test -p codex-api azure_default_store_attaches_ids_and_headers`
## What
Introduce a `CodexResponsesMetadata` struct that defines all the core
metadata we send to Responses API. Example fields are `thread_id`,
`turn_id`, `window_id`, etc.

Going forward, `client_metadata["x-codex-turn-metadata"]` will be the
canonical way Codex sends metadata to Responses API across both HTTP and
websocket transports.

For now, we continue to emit the existing top-level HTTP headers and
top-level `client_metadata` fields from the same
`CodexResponsesMetadata` struct for compatibility reasons.

Also, app-server clients who specify additional
`responsesapi_client_metadata` via `turn/start` and `turn/steer` will
have those fields merged into
`client_metadata["x-codex-turn-metadata"]`, but cannot override the
reserved fields that core uses (i.e. the fields in
`CodexResponsesMetadata`).

## Why

Responses API request instrumentation is the source of truth for
downstream Codex analytics that join requests by Codex IDs such as
session, thread, turn, and context window. Before this change, those
values were assembled through several request-specific paths: HTTP
request bodies, websocket handshake headers, websocket `response.create`
payloads, compaction requests, and the rich `x-codex-turn-metadata`
envelope all had their own wiring.

That made metadata propagation easy to drift across API-key/direct
Responses API requests, ChatGPT-auth/proxied requests, websocket
requests, and compaction requests. It also made additions like
`window_id` error-prone because a field could be added to one transport
projection but missed in another.

## What changed

- Added `CodexResponsesMetadata` as the core-owned snapshot for Codex
metadata sent to ResponsesAPI.
- Render `client_metadata["x-codex-turn-metadata"]`, flat
`client_metadata` projections, and direct compatibility headers from
that same snapshot.
- Include the known Codex-owned fields in the turn metadata blob,
including installation/session/thread/turn/window IDs, request kind,
lineage, sandbox/workspace metadata, timing, and compaction details.
- Treat app-server `responsesapi_client_metadata` as enrichment for the
Codex turn metadata blob while preventing those extras from overriding
Codex-owned fields.
- Use the same metadata path for normal turns, websocket prewarm, local
compaction, remote v1 compaction, and remote v2 compaction.
- Keep websocket connection-only preconnect metadata separate so
handshakes carry compatibility identity headers without inventing a fake
turn metadata blob.

## Verification

- `cargo check -p codex-core`
- `just fix -p codex-core`
## Why

Compaction window identity is part of session history, not model-client
transport state. Persisting it with the compacted rollout item lets
resumed threads continue from the reconstructed window without keeping
mutable window state on `ModelClient`.

## What changed

- Added `window_id` to `CompactedItem` and stamp it when
`replace_compacted_history` installs compacted history.
- Moved auto-compact window id ownership into `AutoCompactWindow` /
`SessionState`; `ModelClient` now receives the request window id from
callers instead of storing it.
- Returned `window_id` from rollout reconstruction for resume.
Reconstruction uses the newest surviving compacted item's stored
`window_id` when present, and falls back to the legacy compacted-item
count when it is absent.
- Kept fork startup at the fresh default window id and updated direct
model-client tests to pass explicit test window ids.

## Validation

- `cargo check -p codex-core --tests`
## Why

Memory startup used hardcoded OpenAI model slugs for extraction and
consolidation. That works for the default OpenAI-compatible path, but
provider-specific backends can require different model identifiers. In
particular, Amazon Bedrock should use its Bedrock model ID for these
background memory requests instead of the OpenAI `gpt-5.4-mini` /
`gpt-5.4` slugs.

## What Changed

- Added provider-owned preferred memory model methods alongside
`approval_review_preferred_model`.
- Updated memory extraction and consolidation to resolve their default
model through the active `ModelProvider`.
- Added Amazon Bedrock overrides so both memory stages use
`openai.gpt-5.4` through Bedrock’s provider-specific model ID.
- Kept explicit `memories.extract_model` and
`memories.consolidation_model` config overrides taking precedence.
- Added startup coverage for default OpenAI and Bedrock memory model
selection.

#closes #26288
## Why

CCA is moving toward a split runtime where the orchestrator may not have
a filesystem, while executors can expose preinstalled plugins and
skills. A thread therefore needs to select capabilities without asking
app-server or core to interpret executor-owned paths through the
orchestrator's filesystem.

The longer-term model is broader than executor skills:

- A plugin is a bundle of skills, MCP servers, connectors/apps, and
hooks.
- A plugin root can be local, executor-owned, or hosted by a backend.
- Components inside one plugin can use different access and execution
mechanisms. A skill may be read from a filesystem or through backend
tools; an HTTP MCP server can run without an executor; a stdio MCP
server or hook needs an execution environment.
- Core should carry generic extension initialization data. The extension
that owns a component should discover it, expose it to the model, and
invoke it through the appropriate runtime.

This PR establishes that architecture through one complete vertical:
selecting a root on an executor, discovering the skills beneath it,
exposing those skills to the model, and reading an explicitly invoked
`SKILL.md` through the same executor.

## Contract

`thread/start` gains an experimental `selectedCapabilityRoots` field:

```json
{
  "selectedCapabilityRoots": [
    {
      "id": "deploy-plugin@1",
      "location": {
        "type": "environment",
        "environmentId": "workspace",
        "path": "/opt/codex/plugins/deploy"
      }
    }
  ]
}
```

The root is intentionally not classified as a "plugin" or "skill" in the
API. It can point at a standalone skill, a directory containing several
skills, or a plugin containing skills and other components. This PR only
teaches the skills extension how to consume it; later extensions can
resolve MCP, connector, and hook components from the same selection.

The platform-supplied `id` is stable selection identity. The location
says which runtime owns the root and gives that runtime an opaque path.
App-server does not inspect or canonicalize the path.

## What changed

### Generic thread extension initialization

App-server converts selected roots into `ExtensionDataInit`. Core
carries that generic initialization value until the final thread ID is
known, then creates thread-scoped `ExtensionData` before lifecycle
contributors run.

This keeps `Session` and core independent of the capability-selection
contract. The initialization value is consumed during construction; it
is not retained as another long-lived `Session` field.

### Executor-backed skills

The skills extension now owns an `ExecutorSkillProvider` that:

- resolves the selected environment through `EnvironmentManager`
- discovers, canonicalizes, and reads skills through that environment's
`ExecutorFileSystem`
- contributes the bounded selected-skill catalog as stable developer
context
- reads an explicitly invoked skill body through the authority that
listed it
- warns when an environment or root is unavailable
- never falls back to the orchestrator filesystem for an executor-owned
root

Skill catalog and instruction fragments have hard byte bounds, which
also bound them below the 10K-token per-item context limit. If a
selected executor skill has the same name as a legacy local skill, the
executor selection owns that invocation and the local body is not
injected a second time.

Existing local and bundled skill loading remains in place. Omitting
`selectedCapabilityRoots` therefore preserves current local-only
behavior.

## Current semantics

- Only environment-owned locations are represented in this first
contract.
- Roots are resolved by the destination extension, not by app-server or
core.
- An unavailable executor or invalid root produces a warning and no
capabilities from that root; it does not trigger a local-filesystem
fallback.
- Selection applies to a newly started active thread.
- MCP servers, connectors, and hooks beneath a selected plugin root are
not activated yet.
- Selection is not yet persisted or inherited across resume, fork, or
subagent creation. Existing local capabilities continue to behave as
they do today in those flows.

## Planned vertical follow-ups

1. **Hosted HTTP MCP:** add an extension-backed HTTP MCP source that
works without an executor, then replace the special-purpose MCP plugins
loader with that implementation.
2. **Executor MCP:** register and execute stdio MCP servers through the
environment that owns the selected plugin root.
3. **Backend skills:** add a hosted skill source whose catalog and
bodies are accessed through extension tools rather than a filesystem.
4. **Connectors and hooks:** activate those components through their
owning extensions, using the same selected-root boundary and
component-specific runtime.
5. **Durable selection:** define the desired-selection lifecycle,
persist it, and make resume, fork, and subagent inheritance explicit
rather than accidental.
6. **Local convergence:** incrementally route existing local plugin,
skill, and MCP loading through the same extension model while preserving
current local behavior.

Each follow-up remains reviewable as an end-to-end capability. The
platform selects roots, generic thread extension data carries the
selection, and the owning extension resolves and operates its component.

## Verification

Coverage added for:

- app-server end-to-end discovery and explicit invocation of a skill
inside an executor-selected plugin root
- exclusive invocation when a selected executor skill collides with a
local skill name
- executor filesystem authority for discovery, canonicalization, and
reads
- thread extension initialization before lifecycle contributors run
- stable executor catalog context, explicit invocation, context
rebuilding, hidden skills, and preserved host/remote catalog behavior

Targeted protocol, core-skills, skills-extension, core lifecycle, and
app-server executor-skill tests were run during development.
## Why

Thread cwd and environment selections are a single logical setting in
core: updating one without the other can silently desynchronize the
next-turn execution context. This change makes that relationship
explicit in the internal thread settings flow while preserving the
existing app-server public API shape.

## What changed

- Moved the cwd/environment pair through internal
`ThreadSettingsOverrides.environment_settings` instead of a top-level
internal `cwd` field.
- Kept `thread/settings/update` public params unchanged, with app-server
translating top-level `cwd` into the paired internal settings shape.
- Moved `Op::UserInput` environment overrides into thread settings so
user turns and settings updates use the same core path.
- Updated core, app-server, MCP, memories, sample, and test callsites to
construct the paired settings shape.

## Verification

- `git diff --check`
- Local test run starting after PR creation.
## Summary
- accept non-empty model-defined reasoning effort values while
preserving built-in effort behavior
- propagate the non-Copy effort type through core, app-server, TUI,
telemetry, and persistence call sites
- preserve string wire encoding and expose an open-string schema for
clients
- update model selection and shortcut behavior for model-advertised
effort values

## Root cause
`ReasoningEffort` gained a string-backed custom variant, so it could no
longer implement `Copy` or rely on derived closed-enum serialization.
Existing consumers still moved effort values from shared references and
assumed a fixed built-in value set.

## Validation
- `just fmt`
- Local tests and compilation were not run per request; relying on CI.
## Summary

Remove the dead experimental `persistExtendedHistory` app-server flag
and collapse rollout persistence to the single policy app-server already
used.

## What Changed

- Removed `persistExtendedHistory` from v2 thread start/resume/fork
params and deleted its deprecation notice path.
- Removed the persistence-mode enums and plumbing through core, rollout,
and thread-store.
- Made rollout filtering mode-free, keeping the existing limited
persisted-history behavior.

## Test Plan

- `just write-app-server-schema`
- `cargo nextest run --no-fail-fast -p codex-app-server-protocol
schema_fixtures`
- `cargo nextest run --no-fail-fast -p codex-app-server
thread_shell_command_history_responses_exclude_persisted_command_executions`
- `cargo nextest run --no-fail-fast -p codex-rollout -p
codex-thread-store`
- final `rg` for removed flag/type names
## Why

This PR
https://github.com/openai/codex/pull/24161#discussion_r3325692763
revealed a subagent data modeling issue, where we overloaded
`forked_from_id` to also mean `parent_thread_id`. That's incorrect since
guardian and review subagents can be a subagent and NOT fork the main
thread's history.

The solution here is to explicitly store a new `parent_thread_id` on
`SessionMeta`, alongside `forked_from_id` which already exists. While
we're at it, also expose it in the app-server protocol on the `Thread`
object.

A thread->subagent relationship and a fork of thread history are
orthogonal concepts.

## What Changed

- Added top-level `parent_thread_id` persistence on `SessionMeta` and
runtime/session plumbing through `SessionConfiguredEvent`,
`CodexSpawnArgs`, `SessionConfiguration`, `ThreadConfigSnapshot`,
`TurnContext`, and `ModelClient`.
- Made turn metadata, request headers, analytics, and subagent-start
events read the separate runtime/top-level parent field instead of
deriving general parent lineage from `SessionSource` or
`forked_from_thread_id`.
- Passed parent lineage separately at delegated subagent, review,
guardian, agent-job, and multi-agent spawn construction sites;
copied-history fork lineage remains derived only from `InitialHistory`.
- Persisted and exposed parent lineage through rollout/thread-store
projections and app-server v2 `Thread.parentThreadId`.
- Updated app-server README text and regenerated app-server schema
fixtures for the additive `parentThreadId` response field.
## Summary
- Add `request_kind` values for foreground turn, startup prewarm,
compaction, and detached memory model requests.
- Attach compaction dispatch metadata to local Responses, legacy
`/v1/responses/compact`, and remote v2 compact requests.
- Add the existing logical context-window identifier as `window_id` on
turn-owned model request metadata.
- Keep identity fields optional for detached memory requests, while
still emitting `request_kind="memory"` in non-git/no-sandbox workspaces.

## Root Cause
`x-codex-turn-metadata` has more than one producer. Foreground turns and
compaction requests own a real turn and should carry that turn identity.
Detached memory stage-one requests do not own a foreground turn, so
absent identity fields are valid rather than missing data. Startup
websocket prewarm is also a model request, but it has `generate=false`
and must not be counted as a foreground turn.

`thread_source` or session source identifies where a thread came from
(for example review, guardian, or another subagent). `request_kind`
identifies what the current outbound model request is doing (`turn`,
`prewarm`, `compaction`, or `memory`). A review or guardian thread can
issue either a normal turn request or a compaction request, so source
cannot replace request kind.

## Behavior / Impact
- Ordinary foreground requests send `request_kind="turn"`, their real
identity fields, and `window_id="<thread_id>:<window_generation>"`.
- Startup websocket warmup requests send `request_kind="prewarm"` so
they are not counted as foreground turns.
- Compaction requests send `request_kind="compaction"`, their real
owning turn identity, the existing `window_id`, and
`compaction.{trigger,reason,implementation,phase,strategy}`.
- Detached memory stage-one requests send `request_kind="memory"`
without `session_id`, `thread_id`, `turn_id`, or `window_id`; when no
workspace metadata exists, the kind-only header is still emitted.
- `session_id`, `thread_id`, `turn_id`, and `window_id` remain optional
in the header schema because detached memory requests do not own a
foreground turn or context window.
- `window_id` is not a new ID system: it is copied from the already-sent
`x-codex-window-id` / WS client metadata value at model-request dispatch
time.
- Existing `x-codex-window-id` HTTP/WS emission, value format,
generation advancement, resume behavior, and fork reset behavior are
unchanged.
- `request_kind`, `window_id`, and upstream turn-owned identity fields
remain schema-owned; input `responsesapi_client_metadata` cannot replace
their canonical values.
- No table, DAG, export, app-server API, or MCP `_meta` schema changes
are included.

A compaction attempt stopped by a pre-compact hook issues no model
request and therefore has no request header; its outcome remains in
analytics events. Status, error, duration, and token deltas also remain
analytics fields rather than request-header fields.

Future detached-memory attribution using a real initiating turn ID as
`trigger_turn_id` is intentionally not part of this PR.

## Sync With Main
- Final pushed head `716342e79` is rebased onto `origin/main@0d37db4b2`.
- The metadata conflict came from upstream `#24160`, which added
`forked_from_thread_id` on the same `turn_metadata` surface. Resolution
preserves that field and its protection from client metadata override
alongside this PR's request-kind, compaction, and window-id fields.
- While resolving the overlapping commits, I removed an accidental
recursive model-request overlay and a duplicate detached-memory header
builder before completing the rebase.

## Latency / User Experience Boundary
- Foreground turns perform no new filesystem, git, or network work. New
fields are inserted into metadata already serialized for outgoing
requests.
- Compaction issues the same model/HTTP requests with the same prompt,
model, service tier, and sampling settings; only metadata bytes change.
- Startup prewarm already sent metadata; it is now correctly classified
as `prewarm`.
- Non-git detached memory now sends a small kind-only metadata header
rather than no header.
- This client diff adds no user-visible latency mechanism beyond
negligible serialization and header bytes on already-existing requests.

## Validation
On conflict-resolved head `1d35c2cfb` based on `origin/main@487521733`:
- `just fmt` (passed)
- `just fix -p codex-core` (passed)
- `git diff --check origin/main...HEAD` (passed)
- `just test -p codex-core -E 'test(turn_metadata) |
test(websocket_first_turn_uses_startup_prewarm_and_create) |
test(responses_stream_includes_turn_metadata_header_for_git_workspace_e2e)
|
test(responses_websocket_forwards_turn_metadata_on_initial_and_incremental_create)
| test(remote_compact_v2_retries_failures_with_stream_retry_budget) |
test(window_id_advances_after_compact_persists_on_resume_and_resets_on_fork)'`
(`23 passed`; `bench-smoke` passed)
- `just test -p codex-app-server -E
'test(turn_start_forwards_client_metadata_to_responses_request_v2) |
test(turn_start_forwards_client_metadata_to_responses_websocket_request_body_v2)
| test(auto_compaction_remote_emits_started_and_completed_items)'` (`3
passed`; `bench-smoke` passed)
- `just test -p codex-memories-write` (`29 passed`; `bench-smoke`
passed)
## Summary

Adds experimental `additionalContext` support to `turn/start` and
`turn/steer` so clients can provide ephemeral external context, such as
browser or automation state, without turning that plumbing into a
visible user prompt or triggering user-prompt lifecycle behavior.

## API Shape

The parameter shape is:

```ts
additionalContext?: Record<string, {
  value: string
  kind: "untrusted" | "application"
}> | null
```

Example:

```json
{
  "additionalContext": {
    "browser_info": {
      "value": "Active tab is CI failures.",
      "kind": "untrusted"
    },
    "automation_info": {
      "value": "CI rerun is in progress.",
      "kind": "application"
    }
  }
}
```

The keys are opaque and caller-defined.

## Context Injection

When provided, accepted entries are inserted into model context as
hidden contextual message items, not as visible thread user-message
items.

`kind: "untrusted"` entries are inserted with role `user`:

```text
<external_${key}>${value}</external_${key}>
```

`kind: "application"` entries are inserted with role `developer`:

```text
<${key}>${value}</${key}>
```

Values are not escaped. Each value is truncated to 1k approximate tokens
before wrapping.

For `turn/start`, accepted additional context is inserted before normal
user input. For `turn/steer`, additional context is merged only when the
steer includes non-empty user input; context-only steers still reject as
empty input.

## Dedupe Strategy

`AdditionalContextStore` lives on session state and stores the latest
complete additional-context map.

Each `turn/start` or non-empty `turn/steer` treats its
`additionalContext` as the current complete set of values. Entries are
injected only when the key is new or the exact entry for that key
changed, including `value` or `kind`. After merging, the store is
replaced with the provided map, so omitted keys are removed from the
retained set and can be injected again later if reintroduced.

Omitting `additionalContext`, passing `null`, or passing an empty object
resets the store to empty and injects nothing.

## What Changed

- Threads experimental v2 `additionalContext` through app-server into
core turn start and steer handling.
- Adds separate contextual fragment types for untrusted user-role
context and application developer-role context.
- Uses pending response input items so additional context can be
combined with normal user input without treating it as prompt text.
- Adds integration coverage for start/steer flow, role routing,
dedupe/reset behavior, deletion/re-add behavior, hook-blocked input
behavior, empty context-only steer rejection, external-fragment marker
matching, and truncation.
**Stack position:** [1 of 7]

## Summary

The first three PRs in this stack are a cleanup pass before the actual
thread settings API work.

Today, core has several overlapping "user input" ops: `UserInput`,
`UserInputWithTurnContext`, and `UserTurn`. They differ mostly in how
much next-turn state they carry, which makes the later queued thread
settings update harder to reason about and review.

This PR starts that cleanup by adding the shared
`ThreadSettingsOverrides` payload and allowing `Op::UserInput` to carry
it. Existing variants remain in place here, so this layer is mostly a
behavior-preserving API shape change plus mechanical constructor
updates.

## End State After PR3

By the end of PR3, `Op::UserInput` is the only "user input" core op. It
can carry optional thread settings overrides for callers that need to
update stored defaults with a turn, while callers without updates use
empty settings. `Op::UserInputWithTurnContext` and `Op::UserTurn` are
deleted.

## End State After PR5

By the end of PR5, core will have only two ops for this area:

- `Op::UserInput` for user-input-bearing submissions.
- `Op::ThreadSettings` for settings-only updates.

## Stack

1. [1 of 7] [Add thread settings to
UserInput](https://github.com/openai/codex/pull/23080) (this PR)
2. [2 of 7] [Remove
UserInputWithTurnContext](https://github.com/openai/codex/pull/23081)
3. [3 of 7] [Remove
UserTurn](https://github.com/openai/codex/pull/23075)
4. [4 of 7] [Placeholder for OverrideTurnContext
cleanup](https://github.com/openai/codex/pull/23087)
5. [5 of 7] [Replace OverrideTurnContext with
ThreadSettings](https://github.com/openai/codex/pull/22508)
6. [6 of 7] [Add app-server thread settings
API](https://github.com/openai/codex/pull/22509)
7. [7 of 7] [Sync TUI thread
settings](https://github.com/openai/codex/pull/22510)
## Summary
TL;DR: teaches `codex-rs` / app-server to request a desktop-provided
attestation token and attach it as `x-oai-attestation` on the scoped
ChatGPT Codex request paths.
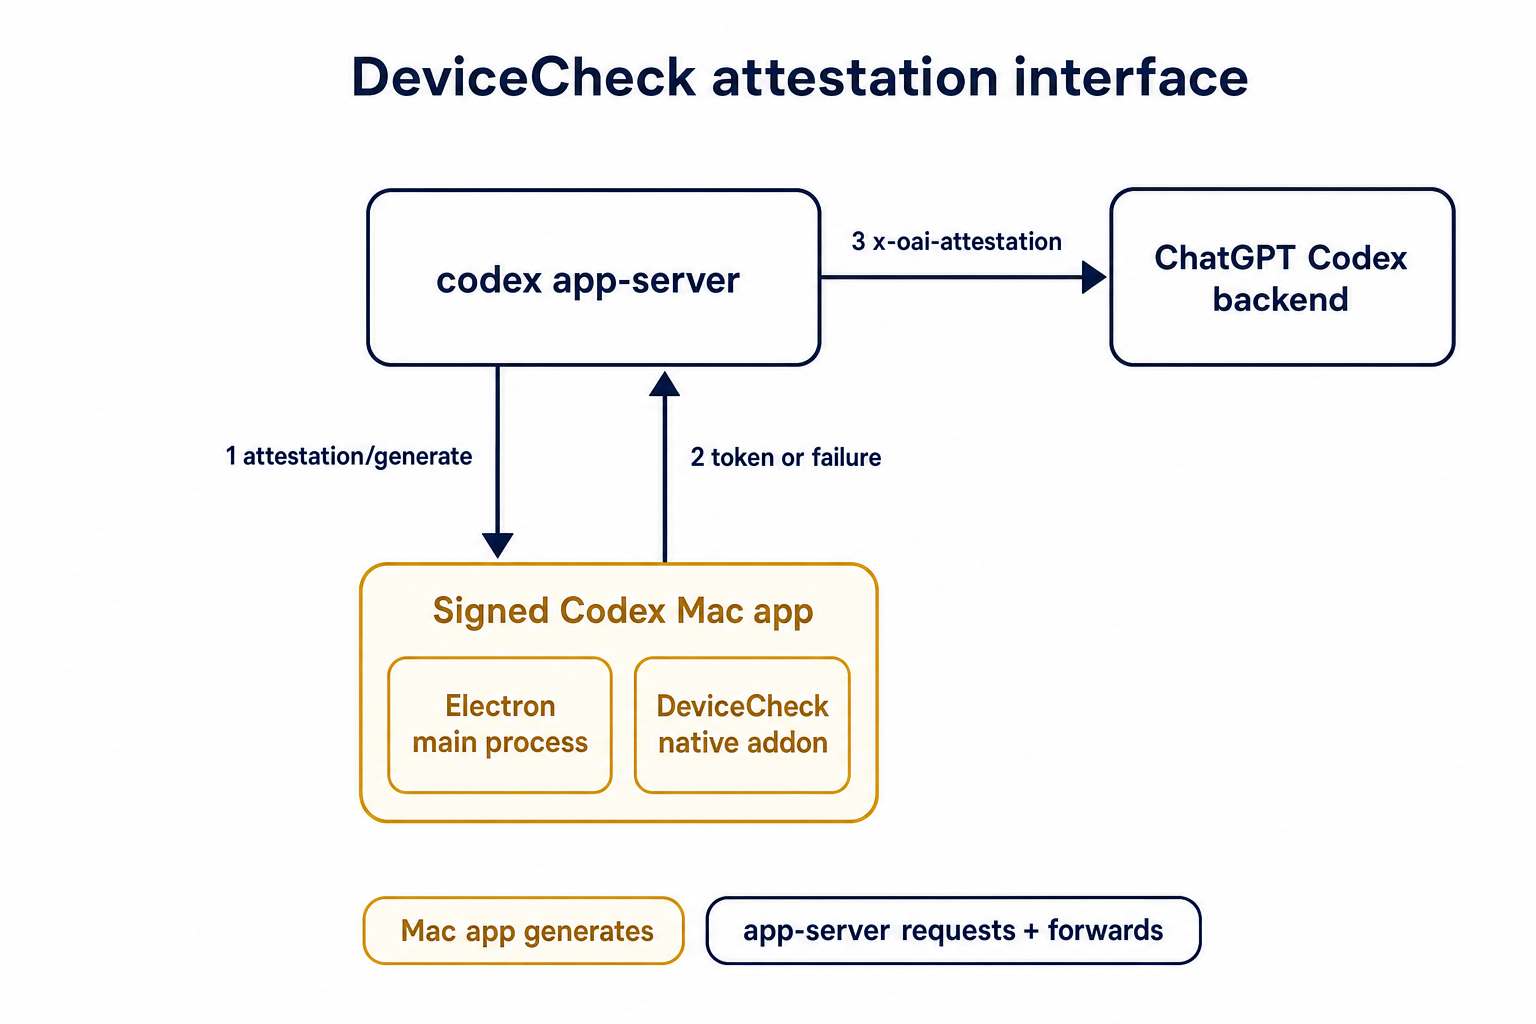
## Details
This PR teaches the Codex app-server runtime how to request and attach
an attestation token. It does not generate DeviceCheck tokens directly;
instead, it relies on the connected desktop app to advertise that it can
generate attestation and then asks that app for a fresh header value
when needed.
The flow is:
1. The Codex desktop app connects to app-server.
2. During `initialize`, the app can advertise that it supports
`requestAttestation`.
3. Before app-server calls selected ChatGPT Codex endpoints, it sends
the internal server request `attestation/generate` to the app.
4. app-server receives a pre-encoded header value back.
5. app-server forwards that value as `x-oai-attestation` on the scoped
outbound requests.
The code in this repo is mostly protocol and runtime plumbing: it adds
the app-server request/response shape, introduces an attestation
provider in core, wires that provider into Responses / compaction /
realtime setup paths, and covers the intended scoping with tests. The
signed macOS DeviceCheck generation remains owned by the desktop app PR.
## Related PR
- Codex desktop app implementation:
https://github.com/openai/openai/pull/878649
## Validation
<details>
<summary>Tests run</summary>
```sh
cargo test -p codex-app-server-protocol
cargo test -p codex-core attestation --lib
cargo test -p codex-app-server --lib attestation
```
Also ran:
```sh
just fix -p codex-core
just fix -p codex-app-server
just fix -p codex-app-server-protocol
just fmt
just write-app-server-schema
```
</details>
<details>
<summary>E2E DeviceCheck validation</summary>
First validated the signed desktop app boundary directly: launched a
packaged signed `Codex.app`, sent `attestation/generate`, decoded the
returned `v1.` attestation header, and validated the extracted
DeviceCheck token with `personal/jm/verify_devicecheck_token.py` using
bundle ID `com.openai.codex`. Apple returned `status_code: 200` and
`is_ok: true`.
Then ran the fuller app + app-server flow. The packaged `Codex.app`
launched a current-branch app-server via `CODEX_CLI_PATH`, and a local
MITM proxy intercepted outbound `chatgpt.com` traffic. The app-server
requested `attestation/generate` from the real Electron app process, and
the intercepted `/backend-api/codex/responses` traffic included
`x-oai-attestation` on both routes:
```text
GET /backend-api/codex/responses Upgrade: websocket x-oai-attestation: present
POST /backend-api/codex/responses Upgrade: none x-oai-attestation: present
```
The captured header decoded to a DeviceCheck token that also validated
with Apple for `com.openai.codex` (`status_code: 200`, `is_ok: true`,
team `2DC432GLL2`).
</details>
---------
Co-authored-by: Codex <noreply@openai.com>
## Summary

Related to
https://openai.slack.com/archives/C095U48JNL9/p1777537279707449
TLDR:
We update the meaning of session ids and thread ids:
* thread_id stays as now
* session_id become a shared id between every thread under a /root
thread (i.e. every sub-agent share the same session id)

This PR introduces an explicit `SessionId` and threads it through the
protocol/client boundary so `session_id` and `thread_id` can diverge
when they need to, while preserving compatibility for older serialized
`session_configured` events.

---------

Co-authored-by: Codex <noreply@openai.com>
## Summary
- make `thread_source` an explicit optional thread-level field on
`thread/start`, `thread/fork`, and returned thread payloads
- persist `thread_source` in rollout/session metadata so resumed live
threads retain the original value
- replace the old best-effort `session_source` -> `thread_source`
mapping with an explicit caller-supplied analytics classification

## Why
Before this change, analytics `thread_source` was populated by a
best-effort mapping from `session_source`. `session_source` describes
the runtime/client surface, not the actual thread-level origin, so that
projection was not accurate enough to distinguish cases such as `user`,
`subagent`, `memory_consolidation`, and future thread origins reliably.

Making `thread_source` explicit keeps one thread-level analytics field
while letting callers provide the real classification directly instead
of recovering it indirectly from `session_source`.

## Impact
For new analytics events, `thread_source` now reflects the explicit
thread-level classification supplied by the caller rather than an
inferred value derived from `session_source`. Existing protocol fields
remain optional; callers that omit `threadSource` now produce `null`
instead of a best-effort inferred value.

## Validation
- `just write-app-server-schema`
- `cargo test -p codex-analytics -p codex-core -p
codex-app-server-protocol --no-run`
- `cargo test -p codex-app-server-protocol
generated_ts_optional_nullable_fields_only_in_params`
- `cargo test -p codex-analytics
thread_initialized_event_serializes_expected_shape`
- `cargo test -p codex-core
resume_stopped_thread_from_rollout_preserves_thread_source`
- Build one app-server process ThreadStore from startup config and share
it with ThreadManager and CodexMessageProcessor.
- Remove per-thread/fork store reconstruction so effective thread config
cannot switch the persistence backend.
- Add params to ThreadStore create/resume for specifying thread
metadata, since otherwise the metadata from store creation would be used
(incorrectly).
Summary:
- Add codex-thread-manager-sample, a one-shot binary that starts a
ThreadManager thread, submits a prompt, and prints the final assistant
output.
- Pass ThreadStore into ThreadManager::new and expose
thread_store_from_config for existing callsites.
- Build the sample Config directly with only --model and prompt inputs.

Verification:
- just fmt
- cargo check -p codex-thread-manager-sample -p codex-app-server -p
codex-mcp-server
- git diff --check

Tests: Not run per request.
 Ruslan Nigmatullin
