## Why

This PR
https://github.com/openai/codex/pull/24161#discussion_r3325692763
revealed a subagent data modeling issue, where we overloaded
`forked_from_id` to also mean `parent_thread_id`. That's incorrect since
guardian and review subagents can be a subagent and NOT fork the main
thread's history.

The solution here is to explicitly store a new `parent_thread_id` on
`SessionMeta`, alongside `forked_from_id` which already exists. While
we're at it, also expose it in the app-server protocol on the `Thread`
object.

A thread->subagent relationship and a fork of thread history are
orthogonal concepts.

## What Changed

- Added top-level `parent_thread_id` persistence on `SessionMeta` and
runtime/session plumbing through `SessionConfiguredEvent`,
`CodexSpawnArgs`, `SessionConfiguration`, `ThreadConfigSnapshot`,
`TurnContext`, and `ModelClient`.
- Made turn metadata, request headers, analytics, and subagent-start
events read the separate runtime/top-level parent field instead of
deriving general parent lineage from `SessionSource` or
`forked_from_thread_id`.
- Passed parent lineage separately at delegated subagent, review,
guardian, agent-job, and multi-agent spawn construction sites;
copied-history fork lineage remains derived only from `InitialHistory`.
- Persisted and exposed parent lineage through rollout/thread-store
projections and app-server v2 `Thread.parentThreadId`.
- Updated app-server README text and regenerated app-server schema
fixtures for the additive `parentThreadId` response field.
## Why

We recently added `forked_from_thread_id` which lets us trace where a
thread's _context_ comes from, but we also want to understand subagent
lineage (e.g. which parent thread spawned this subagent? what kind of
subagent is it?) which is orthogonal.

This PR adds `parent_thread_id` and `subagent_kind` to the
`x-codex-turn-metadata` header sent to ResponsesAPI.

## What changed

- Adds `parent_thread_id` and `subagent_kind` to core-owned
`x-codex-turn-metadata`.
- Restores persisted `SessionSource` and `ThreadSource` from resumed
session metadata so cold-resumed subagent threads keep their lineage on
later Responses API requests.
- Centralizes parent-thread extraction on `SessionSource` /
`SubAgentSource` and reuses it in the Responses client, analytics, agent
control, and state parsing paths.
- Extends reserved-key, git-enrichment, thread-spawn, and app-server v2
metadata coverage for the new lineage fields.

## Verification

- Not run locally per request.
- Added focused coverage in `core/src/turn_metadata_tests.rs` and
`app-server/tests/suite/v2/client_metadata.rs`.
Split from the Guardian prompt cache key change. This PR only updates
codex-rs/core/src/client.rs. Validation was not run per request; this
branch is expected to rely on the companion split PRs.
## Summary
- Add `request_kind` values for foreground turn, startup prewarm,
compaction, and detached memory model requests.
- Attach compaction dispatch metadata to local Responses, legacy
`/v1/responses/compact`, and remote v2 compact requests.
- Add the existing logical context-window identifier as `window_id` on
turn-owned model request metadata.
- Keep identity fields optional for detached memory requests, while
still emitting `request_kind="memory"` in non-git/no-sandbox workspaces.

## Root Cause
`x-codex-turn-metadata` has more than one producer. Foreground turns and
compaction requests own a real turn and should carry that turn identity.
Detached memory stage-one requests do not own a foreground turn, so
absent identity fields are valid rather than missing data. Startup
websocket prewarm is also a model request, but it has `generate=false`
and must not be counted as a foreground turn.

`thread_source` or session source identifies where a thread came from
(for example review, guardian, or another subagent). `request_kind`
identifies what the current outbound model request is doing (`turn`,
`prewarm`, `compaction`, or `memory`). A review or guardian thread can
issue either a normal turn request or a compaction request, so source
cannot replace request kind.

## Behavior / Impact
- Ordinary foreground requests send `request_kind="turn"`, their real
identity fields, and `window_id="<thread_id>:<window_generation>"`.
- Startup websocket warmup requests send `request_kind="prewarm"` so
they are not counted as foreground turns.
- Compaction requests send `request_kind="compaction"`, their real
owning turn identity, the existing `window_id`, and
`compaction.{trigger,reason,implementation,phase,strategy}`.
- Detached memory stage-one requests send `request_kind="memory"`
without `session_id`, `thread_id`, `turn_id`, or `window_id`; when no
workspace metadata exists, the kind-only header is still emitted.
- `session_id`, `thread_id`, `turn_id`, and `window_id` remain optional
in the header schema because detached memory requests do not own a
foreground turn or context window.
- `window_id` is not a new ID system: it is copied from the already-sent
`x-codex-window-id` / WS client metadata value at model-request dispatch
time.
- Existing `x-codex-window-id` HTTP/WS emission, value format,
generation advancement, resume behavior, and fork reset behavior are
unchanged.
- `request_kind`, `window_id`, and upstream turn-owned identity fields
remain schema-owned; input `responsesapi_client_metadata` cannot replace
their canonical values.
- No table, DAG, export, app-server API, or MCP `_meta` schema changes
are included.

A compaction attempt stopped by a pre-compact hook issues no model
request and therefore has no request header; its outcome remains in
analytics events. Status, error, duration, and token deltas also remain
analytics fields rather than request-header fields.

Future detached-memory attribution using a real initiating turn ID as
`trigger_turn_id` is intentionally not part of this PR.

## Sync With Main
- Final pushed head `716342e79` is rebased onto `origin/main@0d37db4b2`.
- The metadata conflict came from upstream `#24160`, which added
`forked_from_thread_id` on the same `turn_metadata` surface. Resolution
preserves that field and its protection from client metadata override
alongside this PR's request-kind, compaction, and window-id fields.
- While resolving the overlapping commits, I removed an accidental
recursive model-request overlay and a duplicate detached-memory header
builder before completing the rebase.

## Latency / User Experience Boundary
- Foreground turns perform no new filesystem, git, or network work. New
fields are inserted into metadata already serialized for outgoing
requests.
- Compaction issues the same model/HTTP requests with the same prompt,
model, service tier, and sampling settings; only metadata bytes change.
- Startup prewarm already sent metadata; it is now correctly classified
as `prewarm`.
- Non-git detached memory now sends a small kind-only metadata header
rather than no header.
- This client diff adds no user-visible latency mechanism beyond
negligible serialization and header bytes on already-existing requests.

## Validation
On conflict-resolved head `1d35c2cfb` based on `origin/main@487521733`:
- `just fmt` (passed)
- `just fix -p codex-core` (passed)
- `git diff --check origin/main...HEAD` (passed)
- `just test -p codex-core -E 'test(turn_metadata) |
test(websocket_first_turn_uses_startup_prewarm_and_create) |
test(responses_stream_includes_turn_metadata_header_for_git_workspace_e2e)
|
test(responses_websocket_forwards_turn_metadata_on_initial_and_incremental_create)
| test(remote_compact_v2_retries_failures_with_stream_retry_budget) |
test(window_id_advances_after_compact_persists_on_resume_and_resets_on_fork)'`
(`23 passed`; `bench-smoke` passed)
- `just test -p codex-app-server -E
'test(turn_start_forwards_client_metadata_to_responses_request_v2) |
test(turn_start_forwards_client_metadata_to_responses_websocket_request_body_v2)
| test(auto_compaction_remote_emits_started_and_completed_items)'` (`3
passed`; `bench-smoke` passed)
- `just test -p codex-memories-write` (`29 passed`; `bench-smoke`
passed)
## Why

The turn loop no longer needs to decide when a `ModelClientSession`
should reset its websocket state after compaction. That reset behavior
belongs inside the model client, where the websocket cache and retry
state are owned. The repo guidance now calls this out explicitly so
future changes let the incremental request logic decide whether the
previous request can be reused.

## What Changed

- Removed the `reset_client_session` return value from pre-sampling and
auto-compact helpers in `core/src/session/turn.rs`.
- Changed compaction helpers to return `CodexResult<()>` so callers only
handle success or failure.
- Made `ModelClientSession::reset_websocket_session` private to
`core/src/client.rs`, leaving it callable only from model-client
internals.
- Added `AGENTS.md` guidance not to call `reset_client_session`
unnecessarily.

## Validation

- `just test -p codex-core session::turn`
## Why

`prewarm_websocket` intentionally stays out of rollout inference
tracing, but the next traced websocket request can still reuse the
warmup `response_id` and send an empty `input` delta. If tracing records
that wire payload verbatim, replay sees an incremental request whose
parent was never traced and cannot reconstruct the conversation.

This fixes that at the producer boundary instead of relaxing
`rollout-trace` replay semantics around unresolved
`previous_response_id` values.

## What

- track whether the last websocket response came from an untraced warmup
and clear that state when the websocket session is reset or reconnected
- when a traced websocket request reuses that warmup parent, keep
sending the compressed websocket request on the wire but record the
logical `ResponsesApiRequest` in the rollout trace
- add a regression test that proves replay reconstructs the logical user
message even though the websocket follow-up carries
`previous_response_id = warm-1` with empty `input`
- update `InferenceTraceAttempt::record_started` docs to reflect that
callers may record a logical request rather than the exact transport
payload

## Testing

- `cargo test -p codex-core --test all
responses_websocket_request_prewarm_traces_logical_request`
## Why

Model catalog responses can now advertise a nullable
`default_service_tier` for each model. Codex needs to preserve three
distinct states all the way from config/app-server inputs to inference:

- no explicit service tier, so the client may apply the current model
catalog default when FastMode is enabled
- explicit `default`, meaning the user intentionally wants standard
routing
- explicit catalog tier ids such as `priority`, `flex`, or future tiers

Keeping those states distinct prevents the UI from showing one tier
while core sends another, especially after model switches or app-server
`thread/start` / `turn/start` updates.

## What Changed

- Plumbed `default_service_tier` through model catalog protocol types,
app-server model responses, generated schemas, model cache fixtures, and
provider/model-manager conversions.
- Added the request-only `default` service tier sentinel and normalized
legacy config spelling so `fast` in `config.toml` still materializes as
the runtime/request id `priority`.
- Moved catalog default resolution to the TUI/client side, including
recomputing the effective service tier when model/FastMode-dependent
surfaces change.
- Updated app-server thread lifecycle config construction so
`serviceTier: null` preserves explicit standard-routing intent by
mapping to `default` instead of internal `None`.
- Kept core responsible for validating explicit tiers against the
current model and stripping `default` before `/v1/responses`, without
applying catalog defaults itself.

## Validation

- `CARGO_INCREMENTAL=0 cargo build -p codex-cli`
- `CARGO_INCREMENTAL=0 cargo test -p codex-app-server model_list`
- `cargo test -p codex-tui service_tier`
- `cargo test -p codex-protocol service_tier_for_request`
- `cargo test -p codex-core get_service_tier`
- `RUST_MIN_STACK=8388608 CARGO_INCREMENTAL=0 cargo test -p codex-core
service_tier`
## Why

Remote compaction currently sends a unary `POST /responses/compact` and
waits for the full response before replacing history or emitting the
completed `ContextCompaction` item. Unlike normal `/responses` streaming
requests, this unary compact request had no timeout boundary. If the
backend accepts the request and then stalls before returning a body, the
existing request retry policy never sees a transport error, so the
compact turn can remain stuck after the started item with no completion
or actionable error.

That matches the reported hang shape in issues such as #18363, where
logs show `responses/compact` was posted but no corresponding compact
completion followed. A bounded request timeout gives the existing retry
policy a concrete timeout error to retry instead of letting the user sit
indefinitely on automatic context compaction.

## What

- Add a request timeout to legacy `/responses/compact` calls.
- Size that timeout from the provider stream idle timeout with a
conservative multiplier, so the default compact attempt gets 20 minutes
rather than the 5 minute stream idle window.
- Map API transport timeouts to a request timeout error instead of the
child-process timeout message.

## Testing

- Not run (per request; CI will cover).
## Why

`model_auto_compact_token_limit` has only been able to budget the full
active context. That makes it hard to set a small "growth since
compaction" budget for sessions that preserve a large carried window
prefix: the preserved prefix can consume the whole budget and force
immediate repeated compaction.

This PR adds an opt-in `body_after_prefix` scope so callers can apply
`model_auto_compact_token_limit` to sampled output and later growth
after the current carried prefix, while still forcing compaction before
the full model context window is exhausted.

## What changed

- Adds `AutoCompactTokenLimitScope` with the existing `total` behavior
as the default and a new `body_after_prefix` mode:
[`config_types.rs`](https://github.com/openai/codex/blob/973806b1cb35792555bead994cb3ed94656eb171/codex-rs/protocol/src/config_types.rs#L24-L37).
- Threads `model_auto_compact_token_limit_scope` through config loading,
`Config`, `core-api`, and app-server v2 schema/TypeScript generation.
- Records the first observed input-token count for a `body_after_prefix`
compaction window and uses it as the baseline when deciding whether the
scoped auto-compaction budget is exhausted:
[`turn.rs`](https://github.com/openai/codex/blob/973806b1cb35792555bead994cb3ed94656eb171/codex-rs/core/src/session/turn.rs#L743-L781).
- Keeps a hard context-window cap in `body_after_prefix`, so scoped
budgeting cannot let the active context overrun the usable window.

## Verification

Added compact-suite coverage for the two key behaviors:
`body_after_prefix` does not re-compact just because the carried prefix
is larger than the scoped budget, and it still compacts when the total
active context reaches the configured context window:
[`compact.rs`](https://github.com/openai/codex/blob/973806b1cb35792555bead994cb3ed94656eb171/codex-rs/core/tests/suite/compact.rs#L3003-L3128).
## Why

Compaction now installs replacement history inside the session, but the
turn and compaction callers were still reaching into
`ModelClientSession` to reset websocket transport state after that
install. That made a transport-level reset part of the compaction API
even though websocket incremental request selection already checks
whether the next request is a strict extension of the previous one and
falls back to a full `response.create` when it is not.

## What changed

- Removed the compaction-side calls to `reset_websocket_session` from
`compact.rs` and `session/turn.rs`.
- Simplified pre-sampling and mid-turn compaction helpers so they return
`CodexResult<()>` instead of carrying a reset flag.
- Made `ModelClientSession::reset_websocket_session` private to
`client.rs`, leaving only the websocket timeout recovery path inside the
client as a caller.

## Validation

- `cargo test -p codex-core --test all
responses_websocket_creates_on_non_prefix`
- `cargo test -p codex-core --test all
steered_user_input_waits_for_model_continuation_after_mid_turn_compact`
- `cargo test -p codex-core --test all
pre_sampling_compact_runs_on_switch_to_smaller_context_model`
## Why

`CODEX_RS_SSE_FIXTURE` let integration-style CLI, exec, and TUI tests
bypass the normal Responses transport by reading SSE from local files.
That kept test-only behavior wired through production client code. The
affected tests can stay hermetic by using the existing
`core_test_support::responses` mock server and passing `openai_base_url`
instead.

## What Changed

- Removed the `CODEX_RS_SSE_FIXTURE` flag,
`codex_api::stream_from_fixture`, the `env-flags` dependency, and the
checked-in SSE fixture files.
- Repointed the affected core, exec, and TUI tests at `MockServer` with
the existing SSE event constructors.
- Removed the Bazel test data plumbing for the deleted fixtures and
refreshed cargo/Bazel lock state.

## Verification

- `cargo build -p codex-cli`
- `cargo test -p codex-api`
- `cargo test -p codex-core --test all responses_api_stream_cli`
- `cargo test -p codex-core --test all
integration_creates_and_checks_session_file`
- `cargo test -p codex-exec --test all ephemeral`
- `cargo test -p codex-exec --test all resume`
- `cargo test -p codex-tui --test all
resume_startup_does_not_consume_model_availability_nux_count`
- `just bazel-lock-update`
- `just bazel-lock-check`
- `just fix -p codex-api -p codex-core -p codex-exec -p codex-tui`
- `git diff --check`
## Summary
TL;DR: teaches `codex-rs` / app-server to request a desktop-provided
attestation token and attach it as `x-oai-attestation` on the scoped
ChatGPT Codex request paths.
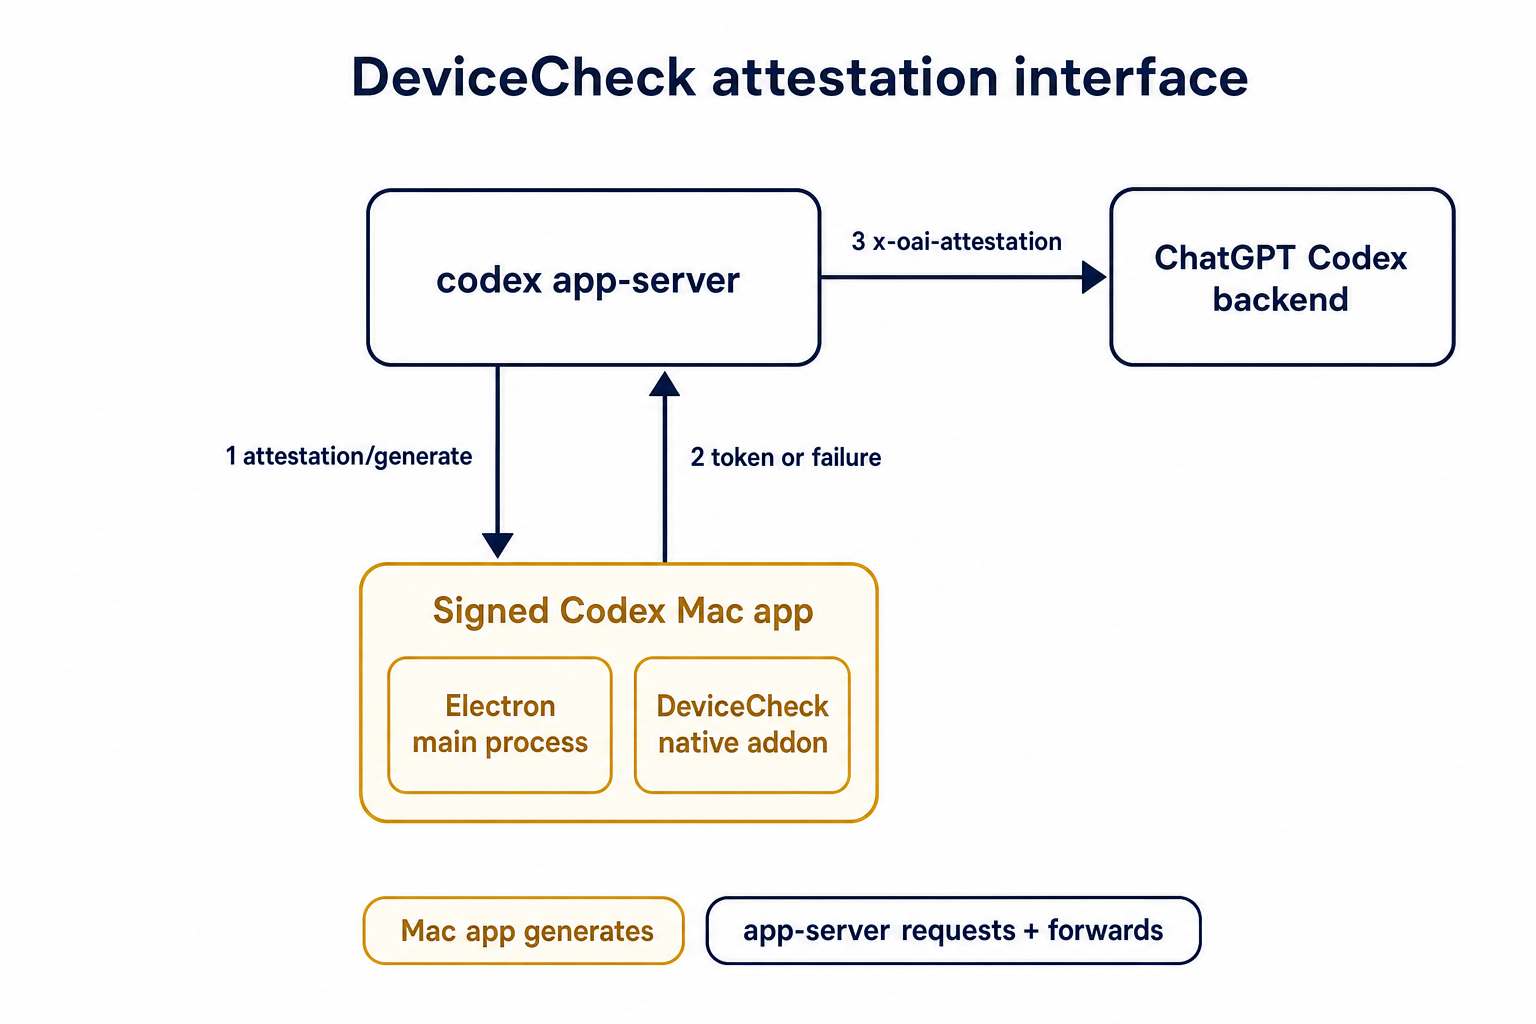
## Details
This PR teaches the Codex app-server runtime how to request and attach
an attestation token. It does not generate DeviceCheck tokens directly;
instead, it relies on the connected desktop app to advertise that it can
generate attestation and then asks that app for a fresh header value
when needed.
The flow is:
1. The Codex desktop app connects to app-server.
2. During `initialize`, the app can advertise that it supports
`requestAttestation`.
3. Before app-server calls selected ChatGPT Codex endpoints, it sends
the internal server request `attestation/generate` to the app.
4. app-server receives a pre-encoded header value back.
5. app-server forwards that value as `x-oai-attestation` on the scoped
outbound requests.
The code in this repo is mostly protocol and runtime plumbing: it adds
the app-server request/response shape, introduces an attestation
provider in core, wires that provider into Responses / compaction /
realtime setup paths, and covers the intended scoping with tests. The
signed macOS DeviceCheck generation remains owned by the desktop app PR.
## Related PR
- Codex desktop app implementation:
https://github.com/openai/openai/pull/878649
## Validation
<details>
<summary>Tests run</summary>
```sh
cargo test -p codex-app-server-protocol
cargo test -p codex-core attestation --lib
cargo test -p codex-app-server --lib attestation
```
Also ran:
```sh
just fix -p codex-core
just fix -p codex-app-server
just fix -p codex-app-server-protocol
just fmt
just write-app-server-schema
```
</details>
<details>
<summary>E2E DeviceCheck validation</summary>
First validated the signed desktop app boundary directly: launched a
packaged signed `Codex.app`, sent `attestation/generate`, decoded the
returned `v1.` attestation header, and validated the extracted
DeviceCheck token with `personal/jm/verify_devicecheck_token.py` using
bundle ID `com.openai.codex`. Apple returned `status_code: 200` and
`is_ok: true`.
Then ran the fuller app + app-server flow. The packaged `Codex.app`
launched a current-branch app-server via `CODEX_CLI_PATH`, and a local
MITM proxy intercepted outbound `chatgpt.com` traffic. The app-server
requested `attestation/generate` from the real Electron app process, and
the intercepted `/backend-api/codex/responses` traffic included
`x-oai-attestation` on both routes:
```text
GET /backend-api/codex/responses Upgrade: websocket x-oai-attestation: present
POST /backend-api/codex/responses Upgrade: none x-oai-attestation: present
```
The captured header decoded to a DeviceCheck token that also validated
with Apple for `com.openai.codex` (`status_code: 200`, `is_ok: true`,
team `2DC432GLL2`).
</details>
---------
Co-authored-by: Codex <noreply@openai.com>
## Why

`/fast` was wired as a one-off slash command even though model metadata
now exposes service tiers as catalog data. That meant adding another
tier, such as a slower/cheaper tier, would require more hardcoded TUI
plumbing instead of letting the model catalog drive the available
commands.

This change makes service-tier commands data-driven: each advertised
`service_tiers` entry becomes a `/name` command using the catalog
description, while the request path sends the tier `id` only when the
selected model supports it.

## What Changed

- Removed the hardcoded `/fast` slash-command variant and introduced
dynamic service-tier command items in the composer and command popup.
- Added toggle behavior for service-tier commands: invoking `/name`
selects that tier, and invoking it again clears the selection.
- Preserved the existing Fast-mode keybinding/status affordances by
resolving the current model tier whose name is `fast`, while still
sending the tier request value such as `priority`.
- Persisted service-tier selections as raw request strings so non-fast
tiers can round-trip through config.
- Updated the Bedrock catalog entry to advertise fast support through
`service_tiers` with `id: "priority"` and `name: "fast"`.
- Added defensive filtering in core so unsupported selected service
tiers are omitted from `/responses` requests.

## Validation

- Added/updated coverage for dynamic service-tier slash command lookup,
popup descriptions, composer dispatch, TUI fast toggling, and
unsupported-tier omission in core request construction.
- Local tests were not run per request.

---------

Co-authored-by: Codex <noreply@openai.com>
## Summary

- Add a `response.processed` websocket request payload and sender for
Responses API websockets.
- Send `response.processed` from `try_run_sampling_request` after a
response completes, local turn processing succeeds, and the
session-owned feature flag is enabled.
- Add websocket coverage for both enabled and disabled feature-flag
behavior.

## Validation

- `just fmt`
- `cargo test -p codex-core response_processed`
- `cargo test -p codex-api responses_websocket`
- `cargo test -p codex-features
responses_websocket_response_processed_is_under_development`
- `git diff --check`
- `just fix -p codex-api -p codex-core -p codex-features`
- `git diff --check origin/main...HEAD`
## Why

`/responses/compact` should preserve the request-affinity fields that
apply to the active auth mode. ChatGPT-auth compact requests need the
effective `service_tier`, and compact requests for every auth mode need
the stable `prompt_cache_key`, so compaction does not quietly lose
routing or cache behavior that normal sampling already has.

This follows the request-parity direction from #20719, but keeps the net
change focused on the compact payload fields needed here.

## What changed

- Add `service_tier` and `prompt_cache_key` to the compact endpoint
input payload.
- Build the remote compact payload from the existing responses request
builder output so `Fast` still maps to `priority` when compact sends a
service tier.
- Pass the turn service tier into remote compaction, but only include it
in compact payloads for ChatGPT-backed auth.
- Keep `prompt_cache_key` on compact payloads for all auth modes.
- Add request-body diff snapshot coverage in
`core/tests/suite/compact_remote.rs` for:
- API-key auth reusing `prompt_cache_key` while omitting `service_tier`
even when `Fast` is configured.
  - ChatGPT auth reusing both `service_tier` and `prompt_cache_key`.
- Drive the snapshot coverage through five varied turns: plain text,
multi-part text, tool-call continuation, image+text input, local-shell
continuation, and final-turn reasoning output.

## Verification

- Added insta snapshots for compact request-body parity against the last
normal `/responses` request after five varied turns.
- Not run locally per repo guidance; relying on GitHub CI for test
execution.

---------

Co-authored-by: Codex <noreply@openai.com>
## Summary

Related to
https://openai.slack.com/archives/C095U48JNL9/p1777537279707449
TLDR:
We update the meaning of session ids and thread ids:
* thread_id stays as now
* session_id become a shared id between every thread under a /root
thread (i.e. every sub-agent share the same session id)

This PR introduces an explicit `SessionId` and threads it through the
protocol/client boundary so `session_id` and `thread_id` can diverge
when they need to, while preserving compatibility for older serialized
`session_configured` events.

---------

Co-authored-by: Codex <noreply@openai.com>
## Why

Feedback reports do not currently surface a direct pointer to the last
model call, so investigations may require searching through many
requests in a session to find the bad response. Preserve the last
model-side IDs at response-stream time so immediate feedback reports
carry that breadcrumb.

## What changed

- Record `last_model_request_id` when a Responses stream exposes an
upstream request ID.
- Record `last_model_response_id` when the model response completes.
- Add unit coverage for the emitted feedback tags.

## Verification

- `cargo test -p codex-core
client::tests::response_stream_records_last_model_feedback_ids`
## Why

`ModelClientSession` and `compact_conversation_history()` were still
rebuilding the same `ResponsesApiRequest` fields separately. That
duplication makes it easy for normal `/responses` turns and compact
requests to drift when request-shape changes land later, which is
exactly the kind of cache-affecting divergence we want to avoid.

This follow-up keeps the scope small by extracting the shared
request-construction logic into one helper and using it from both paths.

## What changed

- move `ResponsesApiRequest` construction into a shared
`ModelClient::build_responses_request(...)` helper in
`core/src/client.rs`
- update the normal `/responses` streaming path to call that helper
instead of the old `ModelClientSession`-local implementation
- update `compact_conversation_history()` to derive its compact payload
from the same helper so `model`, `instructions`, `input`, `tools`,
`parallel_tool_calls`, `reasoning`, and `text` stay aligned with normal
request building
- add a unit test covering the shared helper's prompt cache key,
installation metadata, and `service_tier` behavior

## Verification

- `cargo test -p codex-core
build_responses_request_sets_shared_cache_and_metadata_fields`
- `cargo test -p codex-core --test all
remote_compact_v2_reuses_context_compaction_for_followups`

## Docs

No docs update needed.
## Why

This adds the `remote_compaction_v2` client path so remote compaction
can run through the normal Responses stream and install a
`context_compaction` item that trigger a compaction.

The goal is to migrate some of the compaction logic on the client side

We keeps the v2 transport behind a feature flag while letting follow-up
requests reuse the compacted context instead of falling back to the
legacy compaction item shape.

## What changed

- add `ResponseItem::ContextCompaction` and refresh the generated
app-server / schema / TypeScript fixtures that expose response items on
the wire
- add `core/src/compact_remote_v2.rs` to send compaction through the
standard streamed Responses client, require exactly one
`context_compaction` output item, and install that item into compacted
history
- route manual compact and auto-compaction through the v2 path when
`remote_compaction_v2` is enabled, while keeping the existing remote
compaction path as the fallback
- preserve the new item type across history retention, follow-up request
construction, telemetry, rollout persistence, and rollout-trace
normalization
- add targeted coverage for the feature flag, `context_compaction`
serialization, rollout-trace normalization, and remote-compaction
follow-up behavior

## Verification

- added protocol tests for `context_compaction`
serialization/deserialization in `protocol/src/models.rs`
- added rollout-trace coverage for `context_compaction` normalization in
`rollout-trace/src/reducer/conversation_tests.rs`
- added remote compaction integration coverage for v2 follow-up reuse
and mixed compaction output streams in
`core/tests/suite/compact_remote.rs`

---------

Co-authored-by: Codex <noreply@openai.com>
## Why

Rollout traces need an identifier that can be used to correlate a Codex
inference with upstream Responses API, proxy, and engine logs. The
reduced trace model already exposed `upstream_request_id`, but it was
being populated from the Responses API `response.id`. That value is
useful for `previous_response_id` chaining, but it is not the transport
request id that upstream systems key on.

This PR separates those concepts so trace consumers can reliably answer
both questions:

- which Responses API response did this inference produce?
- which upstream request handled it?

## Structure

The change keeps the upstream request id at the same lifecycle level as
the provider stream:

- `codex-api` captures the `x-request-id` HTTP response header when the
SSE stream is created and exposes it on `ResponseStream`. Fixture and
websocket streams set the field to `None` because they do not have that
HTTP response header.
- `codex-core` carries that stream-level id into `InferenceTraceAttempt`
when recording terminal stream outcomes. Completed, failed, cancelled,
dropped-stream, and pre-response error paths all record the id when it
is available.
- `rollout-trace` now records both identifiers in raw terminal inference
events and response payloads: `response_id` for the Responses API
`response.id`, and `upstream_request_id` for `x-request-id`.
- The reducer stores both fields on `InferenceCall`. It also uses
`response_id` for `previous_response_id` conversation linking, which
removes the old accidental dependency on the misnamed
`upstream_request_id` field.
- Terminal inference reduction now consumes the full terminal payload
(`InferenceCompleted`, `InferenceFailed`, or `InferenceCancelled`) in
one place. That keeps status, partial payloads, response ids, and
upstream request ids consistent across success, failure, cancellation,
and late stream-mapper events.

## Why This Shape

`x-request-id` is a property of the HTTP/provider response envelope, not
an SSE event. Capturing it once in `codex-api` and plumbing it through
terminal trace recording avoids trying to infer the value from stream
contents, and it preserves the id even when the stream fails or is
cancelled after only partial output.

Keeping `response_id` separate from `upstream_request_id` also makes the
reduced trace model less surprising: `response_id` remains the
conversation-continuation id, while `upstream_request_id` is the
operational correlation id for upstream debugging.

## Validation

The PR updates trace and reducer coverage for:

- reading `x-request-id` from SSE response headers;
- storing the true upstream request id on completed inference calls;
- preserving upstream request ids for cancelled and late-cancelled
inference streams;
- keeping `previous_response_id` reconstruction tied to `response_id`
rather than transport request ids.
Keep extracting memories out of core and moving the write trigger in the
app-server
This is temporary and it should move at the client level as a follow-up
This makes core fully independant from `codex-memories-write`

---------

Co-authored-by: Codex <noreply@openai.com>
Records cancelled inference streams when Codex stops consuming a
provider response before `response.completed`, preserving complete
output items observed before cancellation.

Also closes still-running inference calls when the owning turn ends, so
reduced rollout traces do not leave stale `Running` inference nodes.

Covered by focused reducer coverage and a core stream-drop test for
partial output preservation.
Some providers of Responses API forward a model-defined `end_turn`
boolean indicating explicitly the model's indication of whether it would
like to end the turn or to be inferenced again. In this PR, we update
the sampling loop to use this field correctly if it's set. If the field
is not set by the provider, we fall back to the existing sampling logic.
## Summary

Wires rollout trace recording into `codex-core` session and turn
execution. This records the core model request/response, compaction, and
session lifecycle boundaries needed for replay without yet tracing every
nested runtime/tool boundary.

## Stack

This is PR 2/5 in the rollout trace stack.

- [#18876](https://github.com/openai/codex/pull/18876): Add rollout
trace crate
- [#18877](https://github.com/openai/codex/pull/18877): Record core
session rollout traces
- [#18878](https://github.com/openai/codex/pull/18878): Trace tool and
code-mode boundaries
- [#18879](https://github.com/openai/codex/pull/18879): Trace sessions
and multi-agent edges
- [#18880](https://github.com/openai/codex/pull/18880): Add debug trace
reduction command

## Review Notes

This layer is the first live integration point. The important review
question is whether trace recording is isolated from normal session
behavior: trace failures should not become user-visible execution
failures, and recording should preserve the existing turn/session
lifecycle semantics.

The PR depends on the reducer/data model from the first stack entry and
only introduces the core recorder surface that later PRs use for richer
runtime and relationship events.
## Summary

This PR adds `CodexAuth::AgentIdentity` as an explicit auth mode.

An AgentIdentity auth record is a standalone `auth.json` mode. When
`AuthManager::auth().await` loads that mode, it registers one
process-scoped task and stores it in runtime-only state on the auth
value. Header creation stays synchronous after that because the task is
initialized before callers receive the auth object.

This PR also removes the old feature flag path. AgentIdentity is
selected by explicit auth mode, not by a hidden flag or lazy mutation of
ChatGPT auth records.

Reference old stack: https://github.com/openai/codex/pull/17387/changes

## Design Decisions

- AgentIdentity is a real auth enum variant because it can be the only
credential in `auth.json`.
- The process task is ephemeral runtime state. It is not serialized and
is not stored in rollout/session data.
- Account/user metadata needed by existing Codex backend checks lives on
the AgentIdentity record for now.
- `is_chatgpt_auth()` remains token-specific.
- `uses_codex_backend()` is the broader predicate for ChatGPT-token auth
and AgentIdentity auth.

## Stack

1. https://github.com/openai/codex/pull/18757: full revert
2. https://github.com/openai/codex/pull/18871: isolated Agent Identity
crate
3. This PR: explicit AgentIdentity auth mode and startup task allocation
4. https://github.com/openai/codex/pull/18811: migrate Codex backend
auth callsites through AuthProvider
5. https://github.com/openai/codex/pull/18904: accept AgentIdentity JWTs
and load `CODEX_AGENT_IDENTITY`

## Testing

Tests: targeted Rust checks, cargo-shear, Bazel lock check, and CI.
## Summary

Allow guardian to skip other fields and output only
`{"outcome":"allow"}` when the command is low risk.
This change lets guardian reviews use a non-strict text format while
keeping the JSON schema itself as plain user-visible schema data, so
transport strictness is carried out-of-band instead of through a schema
marker key.

## What changed

- Add an explicit `output_schema_strict` flag to model prompts and pass
it into `codex-api` text formatting.
- Set guardian reviewer prompts to non-strict schema validation while
preserving strict-by-default behavior for normal callers.
- Update the guardian output contract so definitely-low-risk decisions
may return only `{"outcome":"allow"}`.
- Treat bare allow responses as low-risk approvals in the guardian
parser.
- Add tests and snapshots covering the non-strict guardian request and
optional guardian output fields.

## Verification

- `cargo test -p codex-core guardian::tests::guardian`
- `cargo test -p codex-core guardian::tests::`
- `cargo test -p codex-core client_common::tests::`
- `cargo test -p codex-protocol
user_input_serialization_includes_final_output_json_schema`
- `cargo test -p codex-api`
- `git diff --check`

Note: `cargo test -p codex-core` was also attempted, but this desktop
environment injects ambient config/proxy state that causes unrelated
config/session tests expecting pristine defaults to fail.

---------

Co-authored-by: Dylan Hurd <dylan.hurd@openai.com>
Co-authored-by: Codex <noreply@openai.com>
## Summary

This PR fully reverts the previously merged Agent Identity runtime
integration from the old stack:
https://github.com/openai/codex/pull/17387/changes

It removes the Codex-side task lifecycle wiring, rollout/session
persistence, feature flag plumbing, lazy `auth.json` mutation,
background task auth paths, and request callsite changes introduced by
that stack.

This leaves the repo in a clean pre-AgentIdentity integration state so
the follow-up PRs can reintroduce the pieces in smaller reviewable
layers.

## Stack

1. This PR: full revert
2. https://github.com/openai/codex/pull/18871: move Agent Identity
business logic into a crate
3. https://github.com/openai/codex/pull/18785: add explicit
AgentIdentity auth mode and startup task allocation
4. https://github.com/openai/codex/pull/18811: migrate auth callsites
through AuthProvider

## Testing

Tests: targeted Rust checks, cargo-shear, Bazel lock check, and CI.
## Summary

This is the AgentAssertion downstream slice for feature-gated agent
identity support, replacing the oversized AgentAssertion slice from PR
#17807.

It isolates task-scoped downstream AgentAssertion wiring on top of the
merged PR3.1 work without re-carrying the earlier agent registration,
task registration, or task-state history.

This PR includes the task-scoped bug-fix call sites from the review:
generic file upload auth, MCP OpenAI file upload auth, and ARC monitor
auth. Broader user/control-plane calls move to PR4.1 and PR4.2.

## Stack

- PR1: https://github.com/openai/codex/pull/17385 - add
`features.use_agent_identity`
- PR2: https://github.com/openai/codex/pull/17386 - register agent
identities when enabled
- PR3: https://github.com/openai/codex/pull/17387 - register agent tasks
when enabled
- PR3.1: https://github.com/openai/codex/pull/17978 - persist and
prewarm registered tasks per thread
- PR4: this PR - use task-scoped `AgentAssertion` downstream when
enabled
- PR4.1: https://github.com/openai/codex/pull/18094 - introduce
AuthManager-owned background/control-plane `AgentAssertion` auth
- PR4.2: https://github.com/openai/codex/pull/18260 - use background
task auth for additional backend/control-plane calls

## What Changed

- add AgentAssertion envelope generation in `codex-core`
- route downstream HTTP and websocket auth through AgentAssertion when
an agent task is present
- extend the model-provider auth provider so non-bearer authorization
schemes can be passed through cleanly
- make generic file uploads attach the full authorization header value
- make MCP OpenAI file uploads use the cached thread agent task
assertion when present
- make ARC monitor calls use the cached thread agent task assertion when
present

## Why

The original PR had drifted ancestry and showed a much larger diff than
the semantic change actually required. Restacking it onto PR3.1 keeps
the reviewable surface down to the downstream assertion slice.

## Validation

- `just fmt`
- `cargo check -p codex-core -p codex-login -p codex-analytics -p
codex-app-server -p codex-cloud-requirements -p codex-cloud-tasks -p
codex-models-manager -p codex-chatgpt -p codex-model-provider -p
codex-mcp -p codex-core-skills`
- `cargo test -p codex-model-provider bearer_auth_provider`
- `cargo test -p codex-core agent_assertion`
- `cargo test -p codex-app-server remote_control`
- `cargo test -p codex-cloud-requirements fetch_cloud_requirements`
- `cargo test -p codex-models-manager manager::tests`
- `cargo test -p codex-chatgpt`
- `cargo test -p codex-cloud-tasks`
- `cargo test -p codex-login agent_identity`
- `just fix -p codex-core -p codex-login -p codex-analytics -p
codex-app-server -p codex-cloud-requirements -p codex-cloud-tasks -p
codex-models-manager -p codex-chatgpt -p codex-model-provider -p
codex-mcp -p codex-core-skills`
- `just fix -p codex-app-server`
- `git diff --check`
## Summary

- Add `codex-model-provider` as the runtime home for model-provider
behavior that does not belong in `codex-core`, `codex-login`, or
`codex-api`.
- The new crate wraps configured `ModelProviderInfo` in a
`ModelProvider` trait object that can resolve the API provider config,
provider-scoped auth manager, and request auth provider for each call.
- This centralizes provider auth behavior in one place today, and gives
us an extension point for future provider-specific auth, model listing,
request setup, and related runtime behavior.

## Tests
Ran tests manually to make sure that provider auth under different
configs still work as expected.

---------

Co-authored-by: pakrym-oai <pakrym@openai.com>
## Summary
- Move auth header construction into the
`AuthProvider::add_auth_headers` contract.
- Inline `CoreAuthProvider` header mutation in its provider impl and
remove the shared header-map helper.
- Update HTTP, websocket, file upload, sideband websocket, and test auth
callsites to use the provider method.
- Add direct coverage for `CoreAuthProvider` auth header mutation.

## Testing
- `just fmt`
- `cargo test -p codex-api`
- `cargo test -p codex-core
client::tests::auth_request_telemetry_context_tracks_attached_auth_and_retry_phase`
- `cargo test -p codex-core` failed on unrelated/reproducible
`tools::handlers::multi_agents::tests::multi_agent_v2_followup_task_interrupts_busy_child_without_losing_message`

---------

Co-authored-by: Celia Chen <celia@openai.com>
Summary:
- parse the realtime call Location header and join that call over the
direct realtime WebSocket
- keep WebRTC starts alive on the existing realtime conversation path

Validation:
- just fmt
- git diff --check
- cargo check -p codex-api
- cargo check -p codex-core --tests
- local cargo tests not run; relying on PR CI
Adds WebRTC startup to the experimental app-server
`thread/realtime/start` method with an optional transport enum. The
websocket path remains the default; WebRTC offers create the realtime
session through the shared start flow and emit the answer SDP via
`thread/realtime/sdp`.

---------

Co-authored-by: Codex <noreply@openai.com>
## Summary

This adds a stable Codex installation ID and includes it on Responses
API requests via `x-codex-installation-id` passed in via the
`client_metadata` field for analytics/debugging.

The main pieces are:
- persist a UUID in `$CODEX_HOME/installation_id`
- thread the installation ID into `ModelClient`
- send it in `client_metadata` on Responses requests so it works
consistently across HTTP and WebSocket transports
## Summary
- reduce public module visibility across Rust crates, preferring private
or crate-private modules with explicit crate-root public exports
- update external call sites and tests to use the intended public crate
APIs instead of reaching through module trees
- add the module visibility guideline to AGENTS.md

## Validation
- `cargo check --workspace --all-targets --message-format=short` passed
before the final fix/format pass
- `just fix` completed successfully
- `just fmt` completed successfully
- `git diff --check` passed
Stacked on #16508.

This removes the temporary `codex-core` / `codex-login` re-export shims
from the ownership split and rewrites callsites to import directly from
`codex-model-provider-info`, `codex-models-manager`, `codex-api`,
`codex-protocol`, `codex-feedback`, and `codex-response-debug-context`.

No behavior change intended; this is the mechanical import cleanup layer
split out from the ownership move.

---------

Co-authored-by: Codex <noreply@openai.com>
## Summary
- split `models-manager` out of `core` and add `ModelsManagerConfig`
plus `Config::to_models_manager_config()` so model metadata paths stop
depending on `core::Config`
- move login-owned/auth-owned code out of `core` into `codex-login`,
move model provider config into `codex-model-provider-info`, move API
bridge mapping into `codex-api`, move protocol-owned types/impls into
`codex-protocol`, and move response debug helpers into a dedicated
`response-debug-context` crate
- move feedback tag emission into `codex-feedback`, relocate tests to
the crates that now own the code, and keep broad temporary re-exports so
this PR avoids a giant import-only rewrite

## Major moves and decisions
- created `codex-models-manager` as the owner for model
cache/catalog/config/model info logic, including the new
`ModelsManagerConfig` struct
- created `codex-model-provider-info` as the owner for provider config
parsing/defaults and kept temporary `codex-login`/`codex-core`
re-exports for old import paths
- moved `api_bridge` error mapping + `CoreAuthProvider` into
`codex-api`, while `codex-login::api_bridge` temporarily re-exports
those symbols and keeps the `auth_provider_from_auth` wrapper
- moved `auth_env_telemetry` and `provider_auth` ownership to
`codex-login`
- moved `CodexErr` ownership to `codex-protocol::error`, plus
`StreamOutput`, `bytes_to_string_smart`, and network policy helpers to
protocol-owned modules
- created `codex-response-debug-context` for
`extract_response_debug_context`, `telemetry_transport_error_message`,
and related response-debug plumbing instead of leaving that behavior in
`core`
- moved `FeedbackRequestTags`, `emit_feedback_request_tags`, and
`emit_feedback_request_tags_with_auth_env` to `codex-feedback`
- deferred removal of temporary re-exports and the mechanical import
rewrites to a stacked follow-up PR so this PR stays reviewable

## Test moves
- moved auth refresh coverage from `core/tests/suite/auth_refresh.rs` to
`login/tests/suite/auth_refresh.rs`
- moved text encoding coverage from
`core/tests/suite/text_encoding_fix.rs` to
`protocol/src/exec_output_tests.rs`
- moved model info override coverage from
`core/tests/suite/model_info_overrides.rs` to
`models-manager/src/model_info_overrides_tests.rs`

---------

Co-authored-by: Codex <noreply@openai.com>
## Why

`codex-core` was re-exporting APIs owned by sibling `codex-*` crates,
which made downstream crates depend on `codex-core` as a proxy module
instead of the actual owner crate.

Removing those forwards makes crate boundaries explicit and lets leaf
crates drop unnecessary `codex-core` dependencies. In this PR, this
reduces the dependency on `codex-core` to `codex-login` in the following
files:

```
codex-rs/backend-client/Cargo.toml
codex-rs/mcp-server/tests/common/Cargo.toml
```

## What

- Remove `codex-rs/core/src/lib.rs` re-exports for symbols owned by
`codex-login`, `codex-mcp`, `codex-rollout`, `codex-analytics`,
`codex-protocol`, `codex-shell-command`, `codex-sandboxing`,
`codex-tools`, and `codex-utils-path`.
- Delete the `default_client` forwarding shim in `codex-rs/core`.
- Update in-crate and downstream callsites to import directly from the
owning `codex-*` crate.
- Add direct Cargo dependencies where callsites now target the owner
crate, and remove `codex-core` from `codex-rs/backend-client`.
## Summary
Fixes#15189.
Custom model providers that set `requires_openai_auth = false` could
only use static credentials via `env_key` or
`experimental_bearer_token`. That is not enough for providers that mint
short-lived bearer tokens, because Codex had no way to run a command to
obtain a bearer token, cache it briefly in memory, and retry with a
refreshed token after a `401`.
This PR adds that provider config and wires it through the existing auth
design: request paths still go through `AuthManager.auth()` and
`UnauthorizedRecovery`, with `core` only choosing when to use a
provider-backed bearer-only `AuthManager`.
## Scope
To keep this PR reviewable, `/models` only uses provider auth for the
initial request in this change. It does **not** add a dedicated `401`
retry path for `/models`; that can be follow-up work if we still need it
after landing the main provider-token support.
## Example Usage
```toml
model_provider = "corp-openai"
[model_providers.corp-openai]
name = "Corp OpenAI"
base_url = "https://gateway.example.com/openai"
requires_openai_auth = false
[model_providers.corp-openai.auth]
command = "gcloud"
args = ["auth", "print-access-token"]
timeout_ms = 5000
refresh_interval_ms = 300000
```
The command contract is intentionally small:
- write the bearer token to `stdout`
- exit `0`
- any leading or trailing whitespace is trimmed before the token is used
## What Changed
- add `model_providers.<id>.auth` to the config model and generated
schema
- validate that command-backed provider auth is mutually exclusive with
`env_key`, `experimental_bearer_token`, and `requires_openai_auth`
- build a bearer-only `AuthManager` for `ModelClient` and
`ModelsManager` when a provider configures `auth`
- let normal Responses requests and realtime websocket connects use the
provider-backed bearer source through the same `AuthManager.auth()` path
- allow `/models` online refresh for command-auth providers and attach
the provider token to the initial `/models` request
- keep `auth.cwd` available as an advanced escape hatch and include it
in the generated config schema
## Testing
- `cargo test -p codex-core provider_auth_command`
- `cargo test -p codex-core
refresh_available_models_uses_provider_auth_token`
- `cargo test -p codex-core
test_deserialize_provider_auth_config_defaults`
## Docs
- `developers.openai.com/codex` should document the new
`[model_providers.<id>.auth]` block and the token-command contract
## Why

This continues the `codex-tools` migration by moving another passive
tool-spec layer out of `codex-core`.

After `ToolSpec` moved into `codex-tools`, `codex-core` still owned
`ConfiguredToolSpec` and `create_tools_json_for_responses_api()`. Both
are data-model and serialization helpers rather than runtime
orchestration, so keeping them in `core/src/tools/registry.rs` and
`core/src/tools/spec.rs` left passive tool-definition code coupled to
`codex-core` longer than necessary.

## What changed

- moved `ConfiguredToolSpec` into `codex-rs/tools/src/tool_spec.rs`
- moved `create_tools_json_for_responses_api()` into
`codex-rs/tools/src/tool_spec.rs`
- re-exported the new surface from `codex-rs/tools/src/lib.rs`, which
remains exports-only
- updated `core/src/client.rs`, `core/src/tools/registry.rs`, and
`core/src/tools/router.rs` to consume the extracted types and serializer
from `codex-tools`
- moved the tool-list serialization test into
`codex-rs/tools/src/tool_spec_tests.rs`
- added focused unit coverage for `ConfiguredToolSpec::name()`
- simplified `core/src/tools/spec_tests.rs` to use the extracted
`ConfiguredToolSpec::name()` directly and removed the now-redundant
local `tool_name()` helper
- updated `codex-rs/tools/README.md` so the crate boundary reflects the
newly extracted tool-spec wrapper and serialization helper

## Test plan

- `cargo test -p codex-tools`
- `CARGO_TARGET_DIR=/tmp/codex-core-configured-spec cargo test -p
codex-core --lib tools::spec::`
- `CARGO_TARGET_DIR=/tmp/codex-core-configured-spec cargo test -p
codex-core --lib client::`
- `just fix -p codex-tools -p codex-core`
- `just argument-comment-lint`

## References

- #15923
- #15928
- #15944
- #15953
- #16031
- #16047
- Move the auth implementation and token data into codex-login.
- Keep codex-core re-exporting that surface from codex-login for
existing callers.

---------

Co-authored-by: Codex <noreply@openai.com>
## Description

Dependent on:
- [responsesapi] https://github.com/openai/openai/pull/760991
- [codex-backend] https://github.com/openai/openai/pull/760985

`codex app-server -> codex-backend -> responsesapi` now reuses a
persistent websocket connection across many turns. This PR updates
tracing when using websockets so that each `response.create` websocket
request propagates the current tracing context, so we can get a holistic
end-to-end trace for each turn.

Tracing is propagated via special keys (`ws_request_header_traceparent`,
`ws_request_header_tracestate`) set in the `client_metadata` param in
Responses API.

Currently tracing on websockets is a bit broken because we only set
tracing context on ws connection time, so it's detached from a
`turn/start` request.
 Owen Lin
