- create `codex-git-utils` and move the shared git helpers into it with
file moves preserved for diff readability
- move the `GitInfo` helpers out of `core` so stacked rollout work can
depend on the shared crate without carrying its own git info module

---------

Co-authored-by: Ahmed Ibrahim <219906144+aibrahim-oai@users.noreply.github.com>
Co-authored-by: Codex <noreply@openai.com>
## Summary
- trim contiguous developer/contextual-user pre-turn updates when
rollback cuts back to a user turn
- add a focused history regression test for the trim behavior
- update the rollback request-boundary snapshots to show the fixed
non-duplicating context shape

---------

Co-authored-by: Codex <noreply@openai.com>
built from #14256. PR description from @etraut-openai:

This PR addresses a hole in [PR
11802](https://github.com/openai/codex/pull/11802). The previous PR
assumed that app server clients would respond to token refresh failures
by presenting the user with an error ("you must log in again") and then
not making further attempts to call network endpoints using the expired
token. While they do present the user with this error, they don't
prevent further attempts to call network endpoints and can repeatedly
call `getAuthStatus(refreshToken=true)` resulting in many failed calls
to the token refresh endpoint.

There are three solutions I considered here:
1. Change the getAuthStatus app server call to return a null auth if the
caller specified "refreshToken" on input and the refresh attempt fails.
This will cause clients to immediately log out the user and return them
to the log in screen. This is a really bad user experience. It's also a
breaking change in the app server contract that could break third-party
clients.
2. Augment the getAuthStatus app server call to return an additional
field that indicates the state of "token could not be refreshed". This
is a non-breaking change to the app server API, but it requires
non-trivial changes for all clients to properly handle this new field
properly.
3. Change the getAuthStatus implementation to handle the case where a
token refresh fails by marking the AuthManager's in-memory access and
refresh tokens as "poisoned" so it they are no longer used. This is the
simplest fix that requires no client changes.

I chose option 3.

Here's Codex's explanation of this change:

When an app-server client asks `getAuthStatus(refreshToken=true)`, we
may try to refresh a stale ChatGPT access token. If that refresh fails
permanently (for example `refresh_token_reused`, expired, or revoked),
the old behavior was bad in two ways:

1. We kept the in-memory auth snapshot alive as if it were still usable.
2. Later auth checks could retry refresh again and again, creating a
storm of doomed `/oauth/token` requests and repeatedly surfacing the
same failure.

This is especially painful for app-server clients because they poll auth
status and can keep driving the refresh path without any real chance of
recovery.

This change makes permanent refresh failures terminal for the current
managed auth snapshot without changing the app-server API contract.

What changed:
- `AuthManager` now poisons the current managed auth snapshot in memory
after a permanent refresh failure, keyed to the unchanged `AuthDotJson`.
- Once poisoned, later refresh attempts for that same snapshot fail fast
locally without calling the auth service again.
- The poison is cleared automatically when auth materially changes, such
as a new login, logout, or reload of different auth state from storage.
- `getAuthStatus(includeToken=true)` now omits `authToken` after a
permanent refresh failure instead of handing out the stale cached bearer
token.

This keeps the current auth method visible to clients, avoids forcing an
immediate logout flow, and stops repeated refresh attempts for
credentials that cannot recover.

---------

Co-authored-by: Eric Traut <etraut@openai.com>
Follow up to #15357 by making proactive ChatGPT auth refresh depend on
the access token's JWT expiration instead of treating `last_refresh` age
as the primary source of truth.
## Summary
- replace the second-compaction test fixtures with a single ordered
`/responses` sequence
- assert against the real recorded request order instead of aggregating
per-mock captures
- realign the second-summary assertion to the first post-compaction user
turn where the summary actually appears

## Root cause
`compact_resume_after_second_compaction_preserves_history` collected
requests from multiple `mount_sse_once_match` recorders. Overlapping
matchers could record the same HTTP request more than once, so the test
indexed into a duplicated synthetic list rather than the true request
stream. That made the summary assertion depend on matcher evaluation
order and platform-specific behavior.

## Impact
- makes the flaky test deterministic by removing duplicate request
capture from the assertion path
- keeps the change scoped to the test only

## Validation
- `just fmt`
- `just argument-comment-lint`
- `env -u CODEX_SANDBOX_NETWORK_DISABLED cargo test -p codex-core
compact_resume_after_second_compaction_preserves_history -- --nocapture`
- repeated the same targeted test 10 times

---------

Co-authored-by: Codex <noreply@openai.com>
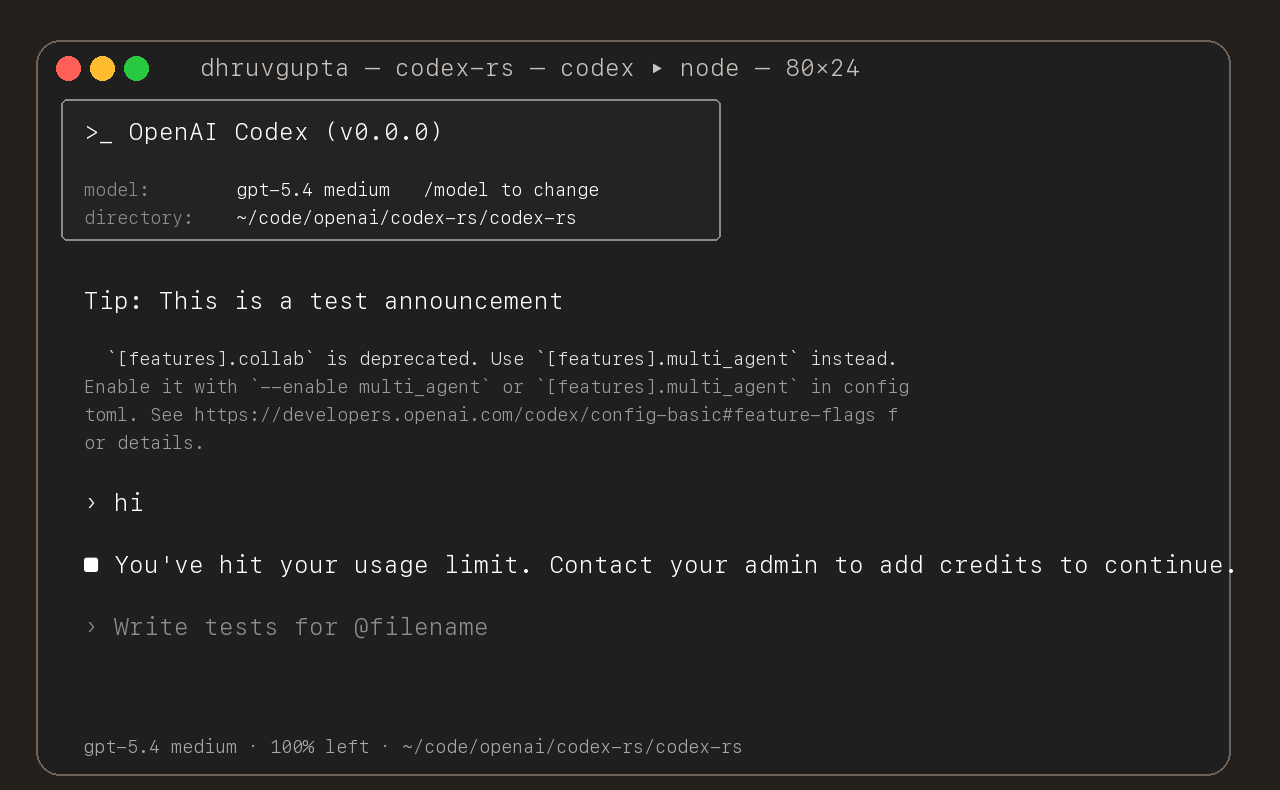
## Summary
- update the self-serve business usage-based limit message to direct
users to their admin for additional credits
- add a focused unit test for the self_serve_business_usage_based plan
branch
Added also:
If you are at a rate limit but you still have credits, codex cli would
tell you to switch the model. We shouldnt do this if you have credits so
fixed this.
## Test
- launched the source-built CLI and verified the updated message is
shown for the self-serve business usage-based plan
## Summary
- add `ForkSnapshotMode` to `ThreadManager::fork_thread` so callers can
request either a committed snapshot or an interrupted snapshot
- share the model-visible `<turn_aborted>` history marker between the
live interrupt path and interrupted forks
- update the small set of direct fork callsites to pass
`ForkSnapshotMode::Committed`

Note: this enables /btw to work similarly as Esc to interrupt (hopefully
somewhat in distribution)

---------

Co-authored-by: Codex <noreply@openai.com>
## What changed
- adds a targeted snapshot test for rollback with contextual diffs in
`codex_tests.rs`
- snapshots the exact model-visible request input before the rolled-back
turn and on the follow-up request after rollback
- shows the duplicate developer and environment context pair appearing
again before the follow-up user message

## Why
Rollback currently rewinds the reference context baseline without
rewinding the live session overrides. On the next turn, the same
contextual diff is emitted again and duplicated in the request sent to
the model.

## Impact
- makes the regression visible in a canonical snapshot test
- keeps the snapshot on the shared `context_snapshot` path without
adding new formatting helpers
- gives a direct repro for future fixes to rollback/context
reconstruction

---------

Co-authored-by: Codex <noreply@openai.com>
## Summary
Adds support for approvals_reviewer to `Op::UserTurn` so we can migrate
`[CodexMessageProcessor::turn_start]` to use Op::UserTurn

## Testing
- [x] Adds quick test for the new field

Co-authored-by: Codex <noreply@openai.com>
- add `PreToolUse` hook for bash-like tool execution only at first
- block shell execution before dispatch with deny-only hook behavior
- introduces common.rs matcher framework for matching when hooks are run

example run:

```
› run three parallel echo commands, and the second one should echo "[block-pre-tool-use]" as a test


• Running the three echo commands in parallel now and I’ll report the output directly.

• Running PreToolUse hook: name for demo pre tool use hook

• Running PreToolUse hook: name for demo pre tool use hook

• Running PreToolUse hook: name for demo pre tool use hook

PreToolUse hook (completed)
  warning: wizard-tower PreToolUse demo inspected Bash: echo "first parallel echo"

PreToolUse hook (blocked)
  warning: wizard-tower PreToolUse demo blocked a Bash command on purpose.
  feedback: PreToolUse demo blocked the command. Remove [block-pre-tool-use] to continue.

PreToolUse hook (completed)
  warning: wizard-tower PreToolUse demo inspected Bash: echo "third parallel echo"

• Ran echo "first parallel echo"
  └ first parallel echo

• Ran echo "third parallel echo"
  └ third parallel echo

• Three little waves went out in parallel.

  1. printed first parallel echo
  2. was blocked before execution because it contained the exact test string [block-pre-tool-use]
  3. printed third parallel echo

  There was also an unrelated macOS defaults warning around the successful commands, but the echoes
  themselves worked fine. If you want, I can rerun the second one with a slightly modified string so
  it passes cleanly.
```
## Summary

Fix a managed ChatGPT auth bug where a stale Codex process could
proactively refresh using an old in-memory refresh token even after
another process had already rotated auth on disk.

This changes the proactive `AuthManager::auth()` path to reuse the
existing guarded `refresh_token()` flow instead of calling the refresh
endpoint directly from cached auth state.

## Original Issue

Users reported repeated `codexd` log lines like:

```text
ERROR codex_core::auth: Failed to refresh token: error sending request for url (https://auth.openai.com/oauth/token)
```

In practice this showed up most often when multiple `codexd` processes
were left running. Killing the extra processes stopped the noise, which
suggested the issue was caused by stale auth state across processes
rather than invalid user credentials.

## Diagnosis

The bug was in the proactive refresh path used by `AuthManager::auth()`:

- Process A could refresh successfully, rotate refresh token `R0` to
`R1`, and persist the updated auth state plus `last_refresh` to disk.
- Process B could keep an older auth snapshot cached in memory, still
holding `R0` and the old `last_refresh`.
- Later, when Process B called `auth()`, it checked staleness from its
cached in-memory auth instead of first reloading from disk.
- Because that cached `last_refresh` was stale, Process B would
proactively call `/oauth/token` with stale refresh token `R0`.
- On failure, `auth()` logged the refresh error but kept returning the
same stale cached auth, so repeated `auth()` calls could keep retrying
with dead state.

This differed from the existing unauthorized-recovery flow, which
already did the safer thing: guarded reload from disk first, then
refresh only if the on-disk auth was unchanged.

## What Changed

- Switched proactive refresh in `AuthManager::auth()` to:
  - do a pure staleness check on cached auth
  - call `refresh_token()` when stale
- return the original cached auth on genuine refresh failure, preserving
existing outward behavior
- Removed the direct proactive refresh-from-cached-state path
- Added regression tests covering:
  - stale cached auth with newer same-account auth already on disk
- the same scenario even when the refresh endpoint would fail if called

## Why This Fix

`refresh_token()` already contains the right cross-process safety
behavior:

- guarded reload from disk
- same-account verification
- skip-refresh when another process already changed auth

Reusing that path makes proactive refresh consistent with unauthorized
recovery and prevents stale processes from trying to refresh
already-rotated tokens.

## Testing

Test shape:

- create a fresh temp `CODEX_HOME` from `~/.codex/auth.json`
- force `last_refresh` to an old timestamp so proactive refresh is
required
- start two long-lived helper processes against the same auth file
- start `B` first so it caches stale auth and sleeps
- start `A` second so it refreshes first
- point both at a local mock `/oauth/token` server
- inspect whether `B` makes a second refresh request with the stale
in-memory token, or reloads the rotated token from disk

### Before the fix

The repro showed the bug clearly: the mock server saw two refreshes with
the same stale token, `A` rotated to a new token, and `B` still returned
the stale token instead of reloading from disk.

```text
POST /oauth/token refresh_token=rt_j6s0...
POST /oauth/token refresh_token=rt_j6s0...

B:cached_before=rt_j6s0...
B:cached_after=rt_j6s0...
B:returned=rt_j6s0...

A:cached_before=rt_j6s0...
A:cached_after=rotated-refresh-token-logged-run-v2
A:returned=rotated-refresh-token-logged-run-v2
```

### After the fix

After the fix, the mock server saw only one refresh request. `A`
refreshed once, and `B` started with the stale token but reloaded and
returned the rotated token.

```text
POST /oauth/token refresh_token=rt_j6s0...

B:cached_before=rt_j6s0...
B:cached_after=rotated-refresh-token-fix-branch
B:returned=rotated-refresh-token-fix-branch

A:cached_before=rt_j6s0...
A:cached_after=rotated-refresh-token-fix-branch
A:returned=rotated-refresh-token-fix-branch
```

This shows the new behavior: `A` refreshes once, then `B` reuses the
updated auth from disk instead of making a second refresh request with
the stale token.
Moves Code Mode to a new crate with no dependencies on codex. This
create encodes the code mode semantics that we want for lifetime,
mounting, tool calling.

The model-facing surface is mostly unchanged. `exec` still runs raw
JavaScript, `wait` still resumes or terminates a `cell_id`, nested tools
are still available through `tools.*`, and helpers like `text`, `image`,
`store`, `load`, `notify`, `yield_control`, and `exit` still exist.

The major change is underneath that surface:

- Old code mode was an external Node runtime.
- New code mode is an in-process V8 runtime embedded directly in Rust.
- Old code mode managed cells inside a long-lived Node runner process.
- New code mode manages cells in Rust, with one V8 runtime thread per
active `exec`.
- Old code mode used JSON protocol messages over child stdin/stdout plus
Node worker-thread messages.
- New code mode uses Rust channels and direct V8 callbacks/events.

This PR also fixes the two migration regressions that fell out of that
substrate change:

- `wait { terminate: true }` now waits for the V8 runtime to actually
stop before reporting termination.
- synchronous top-level `exit()` now succeeds again instead of surfacing
as a script error.

---

- `core/src/tools/code_mode/*` is now mostly an adapter layer for the
public `exec` / `wait` tools.
- `code-mode/src/service.rs` owns cell sessions and async control flow
in Rust.
- `code-mode/src/runtime/*.rs` owns the embedded V8 isolate and
JavaScript execution.
- each `exec` spawns a dedicated runtime thread plus a Rust
session-control task.
- helper globals are installed directly into the V8 context instead of
being injected through a source prelude.
- helper modules like `tools.js` and `@openai/code_mode` are synthesized
through V8 module resolution callbacks in Rust.

---

Also added a benchmark for showing the speed of init and use of a code
mode env:
```
$ cargo bench -p codex-code-mode --bench exec_overhead -- --samples 30 --warm-iterations 25 --tool-counts 0,32,128
Finished [`bench` profile [optimized]](https://doc.rust-lang.org/cargo/reference/profiles.html#default-profiles) target(s) in 0.18s
     Running benches/exec_overhead.rs (target/release/deps/exec_overhead-008c440d800545ae)
exec_overhead: samples=30, warm_iterations=25, tool_counts=[0, 32, 128]
scenario       tools samples    warmups      iters      mean/exec       p95/exec       rssΔ p50       rssΔ max
cold_exec          0      30          0          1         1.13ms         1.20ms        8.05MiB        8.06MiB
warm_exec          0      30          1         25       473.43us       512.49us      912.00KiB        1.33MiB
cold_exec         32      30          0          1         1.03ms         1.15ms        8.08MiB        8.11MiB
warm_exec         32      30          1         25       509.73us       545.76us      960.00KiB        1.30MiB
cold_exec        128      30          0          1         1.14ms         1.19ms        8.30MiB        8.34MiB
warm_exec        128      30          1         25       575.08us       591.03us      736.00KiB      864.00KiB
memory uses a fresh-process max RSS delta for each scenario
```

---------

Co-authored-by: Codex <noreply@openai.com>
This PR add an URI-based system to reference agents within a tree. This
comes from a sync between research and engineering.

The main agent (the one manually spawned by a user) is always called
`/root`. Any sub-agent spawned by it will be `/root/agent_1` for example
where `agent_1` is chosen by the model.

Any agent can contact any agents using the path.

Paths can be used either in absolute or relative to the calling agents

Resume is not supported for now on this new path

